
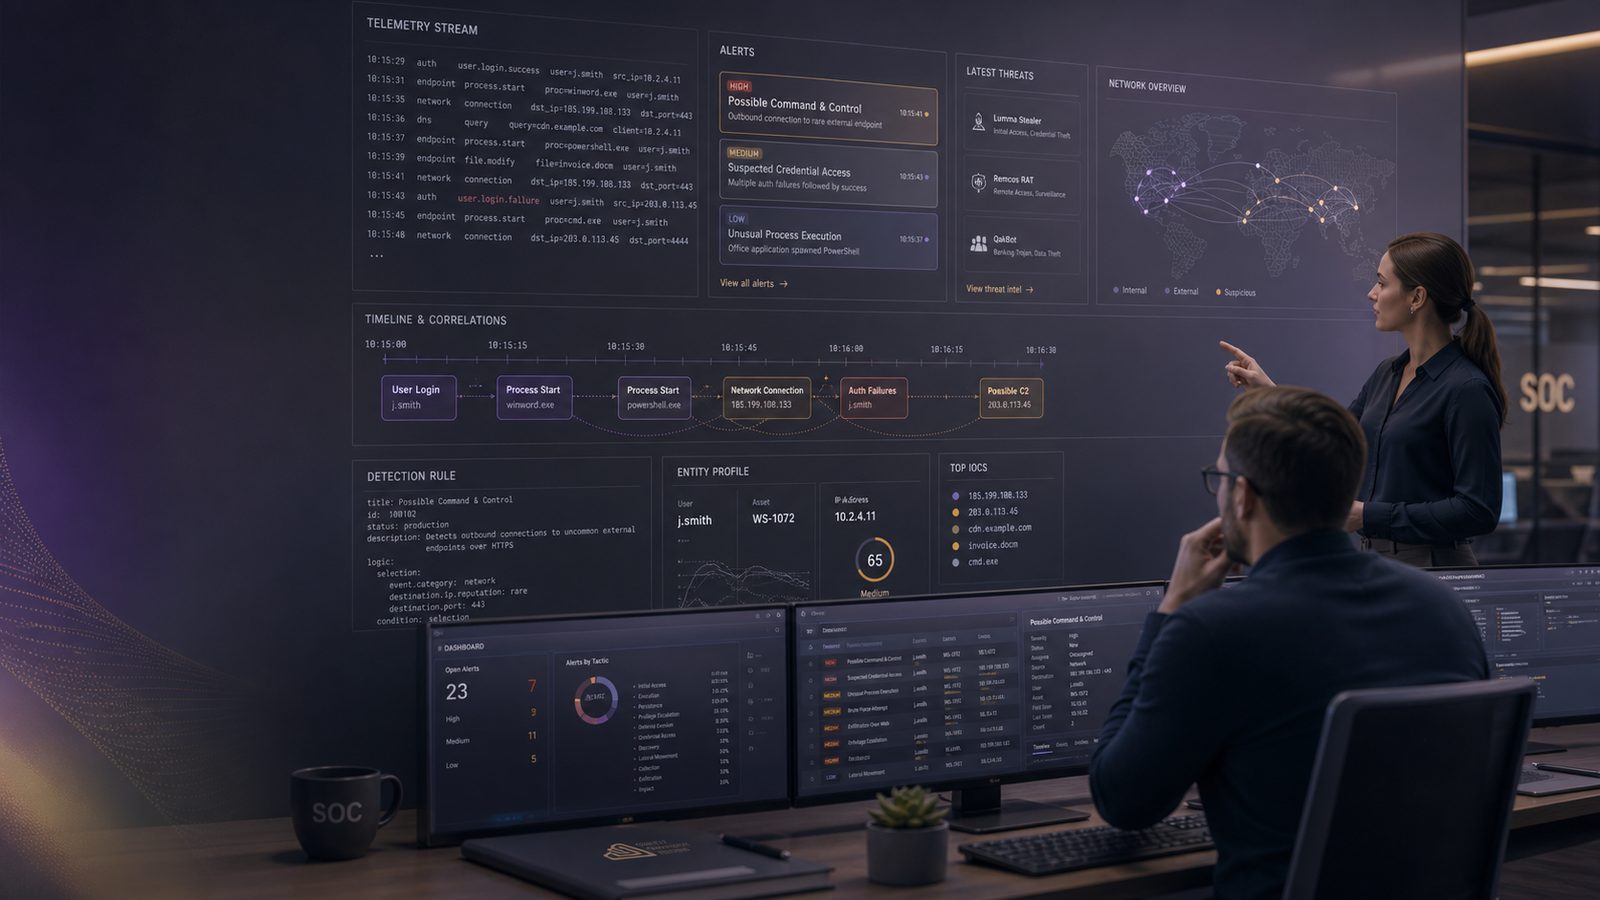
Detection engineering is the discipline of turning attacker behaviour, business context, and available telemetry into reliable detections that a SOC can operate at scale. For many UK SMEs, the challenge is not buying another tool. It is building a repeatable process that produces useful alerts, keeps false positives under control, and improves over time.
That matters because a detection that nobody trusts is almost as bad as no detection at all. If analysts are buried in noisy alerts, they miss the events that actually need attention. If rules are written ad hoc, without clear ownership or validation, they age quickly and become blind to the techniques that matter most. A mature detection programme is therefore part engineering, part operations, and part governance.
It also sits within a wider detect and respond operating model. Good detections support triage, escalation, containment, and investigation. They are not a replacement for incident response, and they are not the same as threat hunting. If you want the operational side of that workflow, it is worth reading our article on incident triage and escalation workflows in SOC operations.
Key takeaways
- Detection engineering is a lifecycle discipline that combines use case design, telemetry, validation, tuning, and retirement.
- Start from threat models and ATT&CK techniques, then map them to the telemetry you actually have.
- High-quality detections need endpoint, identity, cloud, and network data, plus reliable timestamps and consistent logging.
- Measure detections by fidelity, false positives, latency, and operational cost, not just whether they fire.
- Validate safely with purple-team exercises and atomic tests, then keep rules under review as the environment changes.
What detection engineering is and why SOC teams need it
At a practical level, detection engineering is the process of defining a detection hypothesis, identifying the telemetry needed to test it, implementing a rule or analytic, validating the result, and then maintaining it as the environment changes. That is broader than writing a SIEM query. It includes data quality, rule logic, response context, and lifecycle management.
The distinction from alert triage is important. Triage is what happens after an alert fires. The analyst decides whether it is benign, suspicious, or confirmed malicious, then escalates or closes it. Detection engineering happens earlier. It asks whether the alert should exist, whether it fires on the right behaviour, and whether it gives the analyst enough context to act quickly.
It also differs from threat hunting. Hunting is usually hypothesis-driven and exploratory, often looking for weak signals or unknown activity. Detection engineering is more deterministic. You are trying to create a repeatable analytic that will fire when a known behaviour occurs, with an acceptable balance of fidelity and coverage.
For small teams, this distinction helps with prioritisation. A SOC that treats every alert as a one-off investigation will struggle to improve. A SOC that treats detections as products, with owners and review cycles, can steadily reduce noise and improve coverage. That is especially true when detections are aligned to the organisation’s most likely attack paths and the telemetry already available. If you are still working out where your blind spots are, our guide to detection coverage and blind spots is a useful companion piece.
The detection engineering lifecycle
A useful lifecycle has five stages: requirements, implementation, validation, tuning, and retirement. The exact tooling may differ, but the discipline should stay the same.
Requirements start with a use case. For example, you may want to detect suspicious PowerShell execution, abnormal Entra ID sign-ins, or lateral movement from a compromised endpoint. The use case should describe the behaviour, the expected data source, the likely attacker objective, and the operational outcome. In other words, what are you trying to catch, and what should the SOC do when it fires?
Implementation is where the rule is written in the target platform. That may be Sigma for portability, KQL in Microsoft Sentinel, SPL in Splunk, or a vendor-specific query language. The key is to keep the logic readable and to separate signal from presentation. If the platform supports it, enrich alerts with host, user, process, and identity context so the analyst does not need to pivot immediately.
Validation checks whether the rule behaves as intended. This is where many teams stop too early. A rule that fires in a lab is not necessarily useful in production. You need to know whether it fires on the right event, whether it misses variants, and whether it creates excessive noise. We cover the implementation side in more detail in building a detection-as-code pipeline with Sigma and CI/CD.
Tuning is the ongoing work of reducing false positives without removing the behaviour you care about. That often means narrowing scope, adding context, excluding known-good patterns, or changing thresholds. Tuning should be evidence-based. Avoid the temptation to suppress an alert just because it is noisy this week.
Retirement is often overlooked. Detections should be removed when they are superseded, when the underlying telemetry disappears, or when the behaviour is no longer relevant. Keeping dead rules in production creates confusion and wastes analyst time.
Building detections from threat models and ATT&CK coverage
Detection engineering works best when it starts from a threat model rather than from a log source. That means asking which adversary behaviours are most relevant to your environment, then mapping those behaviours to telemetry and analytics.
MITRE ATT&CK is useful here because it gives you a shared vocabulary for attacker techniques. It does not tell you what to detect, but it helps structure the problem. For example, if you are concerned about credential theft, you might look at techniques such as credential dumping, Kerberos abuse, or token theft. If you are concerned about initial access, you might prioritise phishing, valid accounts, or external remote services. The value is in making coverage explicit and testable.
A practical approach is to build a small matrix of priority techniques, the data sources that can observe them, and the current detection status. That can be done manually or with a coverage tool. If you want a structured way to assess this, our article on measuring detection coverage against MITRE ATT&CK using DeTT&CT shows how to turn ATT&CK into a coverage model rather than a slide deck.
Once you have a technique in scope, turn it into a detection hypothesis. For example: if an attacker is using a compromised account to create a scheduled task on a workstation outside normal admin activity, then we should see a task creation event, followed by a process launch, from a user or host that does not normally perform that action. That hypothesis can then be translated into a Sigma rule, a KQL query, or a correlation rule.
The important point is that the hypothesis should be testable. If you cannot describe the expected telemetry, the expected exceptions, and the expected response, the detection is probably too vague to be useful.
What telemetry you need before you can detect reliably
Detections are only as good as the data behind them. For most SMEs, the core telemetry domains are endpoint, identity, cloud, and network. You do not need every possible log source, but you do need enough coverage to observe the behaviours you care about.
Endpoint telemetry usually includes process creation, command-line arguments, parent-child process relationships, script block logging where appropriate, service creation, scheduled task creation, and security-relevant Windows Event Logs. Sysmon is often valuable because it adds higher-fidelity process and network events, but only if it is configured carefully. Too much telemetry without a plan creates cost and noise. If you are refining Windows telemetry, our guide to tuning Sysmon configuration for high-fidelity process telemetry is a good reference point.
Identity telemetry should include authentication events, failed and successful sign-ins, privilege changes, MFA events, conditional access outcomes, and directory audit logs. Identity is often the fastest route to impact in cloud-first environments, so detections that ignore identity are incomplete by design.
Cloud telemetry includes audit logs from Microsoft 365, Entra ID, and other SaaS platforms, plus control-plane activity from infrastructure-as-a-service environments. This is where you spot suspicious consent grants, mailbox rule abuse, API token misuse, and unusual administrative actions.
Network telemetry still matters, especially for command-and-control detection, unusual DNS behaviour, and lateral movement. It is not a replacement for endpoint visibility, but it can catch activity that never reaches the host logs or that is intentionally evasive. For a broader architecture view, see unified threat detection across endpoint, identity, and network.
The most common visibility gaps are predictable: endpoints without process telemetry, identity logs with short retention, cloud audit logs not enabled at the right level, and network sensors that see only a fraction of traffic. Another frequent issue is inconsistent time synchronisation, which makes correlation unreliable. If timestamps are not trustworthy, multi-stage detections become fragile.
Designing detections that are maintainable in practice
Maintainability is where many detection programmes succeed or fail. A clever rule that only one engineer understands is a liability. A slightly simpler rule that the whole team can review, test, and tune is usually better.
Sigma is useful as a detection-as-code format because it separates the detection intent from the backend implementation. A well-written Sigma rule should describe the event source, the selection logic, the filters, and the condition in a way that can be translated into multiple platforms. Keep field names explicit and avoid overcomplicated logic unless the use case really needs it.
In Microsoft Sentinel, KQL is often the practical implementation language. A good KQL analytic should be readable, use joins sparingly, and make the time window explicit. For example, if you are correlating a suspicious sign-in with a subsequent privilege change, define the window in the query rather than relying on implicit assumptions. That makes tuning and review easier.
Correlation logic is especially important for multi-stage attacks. Single-event alerts are useful, but they often lack context. A process creation event may be benign on its own, but if it is followed by credential access, remote service creation, and unusual outbound connections, the combined pattern is much more meaningful. If you are building that style of analytic, our article on writing Sigma correlation rules for multi-stage attack detection goes deeper into the pattern.
Thresholds and suppression strategies need care. Thresholds help reduce noise, but they can also hide low-and-slow activity. Suppression should be targeted and time-bound. For example, suppress a known deployment account during a defined maintenance window, not forever. Where possible, use allow lists based on identity, host group, or change ticket rather than broad exclusions that age badly.
Good detections also include operational context. Add fields such as asset criticality, user role, geolocation, device compliance status, and known-good administrative tools. That context helps analysts decide whether an alert is routine, suspicious, or urgent.
Measuring detection quality
Detection quality is not just about whether a rule fires. It is about whether it produces useful outcomes for the SOC at an acceptable cost.
False positives are alerts that fire on benign activity. Too many false positives increase analyst fatigue and reduce trust. But false positives are not always bad. A rule with a few manageable false positives may still be valuable if it catches high-impact behaviour. The question is whether the ratio is acceptable for the use case.
False negatives are harder to see because they do not generate alerts. You usually measure them indirectly through validation exercises, incident reviews, and coverage analysis. If a technique is in your threat model but there is no reliable telemetry or no working analytic, that is a known gap rather than a hidden success.
Alert fidelity is the proportion of alerts that are genuinely actionable. This is often the most useful metric for a SOC manager because it reflects analyst effort. A high-fidelity alert should provide enough context to support a triage decision without excessive manual investigation.
Latency matters too. If an alert arrives too late, the attacker may already have achieved their objective. Measure the time from event occurrence to alert creation, then from alert creation to analyst review. Both matter, and the second is often overlooked.
Operational cost includes analyst time, SIEM ingestion cost, maintenance effort, and the cost of validating the rule after platform changes. A detection that is technically elegant but expensive to run may not be sustainable for an SME. This is why detection engineering should be treated as an operating discipline, not a one-off project.
For a more structured view of quality metrics, our article on measuring detection quality and false positives is worth using alongside this guide.
Validating detections safely
Validation should be safe, repeatable, and proportionate. The aim is to test the detection logic, not to create unnecessary risk in production.
Purple-team exercises are useful because they combine offensive simulation with defensive verification. The defender can see whether the expected telemetry appears, whether the alert fires, and whether the analyst workflow makes sense. The exercise should be scoped, approved, and logged, with clear rollback steps if anything behaves unexpectedly.
Atomic tests are another practical option. These are small, controlled actions that emulate a specific technique without attempting to replicate a full intrusion. They are useful for checking whether a detection fires on the intended behaviour. Used carefully, they help you validate coverage without overfitting the rule to a single sample.
The key is to avoid building detections that only work against a known test artefact. A good validation process checks for variants, not just exact matches. For example, if a rule detects suspicious PowerShell, test different command-line patterns, encoded commands, and legitimate administrative use cases. The goal is to understand what the rule really sees.
Validation should also include negative testing. If a rule is supposed to ignore a known deployment tool or a service account, confirm that it does so consistently. That is often where brittle rules fail in production.
Operating detection engineering in a small SOC
In a small SOC, detection engineering usually sits between operations and engineering, even if the same people wear both hats. Someone needs to own the backlog, someone needs to approve changes, and someone needs to review the effect on triage workload.
A practical operating model has three roles, even if they are part-time. First, a detection owner who prioritises use cases and tracks lifecycle status. Second, an analyst or engineer who implements and tunes the rule. Third, a reviewer who checks whether the detection still aligns with business risk and telemetry reality. In a small team, these may all be the same person, but the responsibilities should still be explicit.
Backlog management is important because there will always be more ideas than capacity. Prioritise detections based on business impact, likelihood, and observability. A detection for a high-risk identity technique with good telemetry is usually a better investment than a low-value rule that requires a new data source.
Change control does not need to be bureaucratic, but it should be consistent. Record why the rule exists, what data it depends on, what changed, who approved the change, and how it was validated. That documentation becomes essential when an alert changes behaviour after a platform update or a new endpoint policy.
Documentation should be operational, not theoretical. Include the detection hypothesis, the data sources, the expected false positives, the triage steps, and the escalation criteria. If a new analyst cannot understand the rule quickly, the documentation is not good enough.
Common failure modes and how to avoid them
The most common failure mode is alert fatigue. This usually happens when teams deploy too many rules too quickly, without a clear prioritisation model. The fix is to start with a small number of high-value detections and prove that they are useful before expanding.
Duplicate logic is another problem. It often appears when different teams write similar rules for the same behaviour in different tools. That creates maintenance overhead and inconsistent outcomes. Where possible, define a single detection intent and then translate it into platform-specific implementations.
Poor data quality is a silent killer. Missing fields, inconsistent hostnames, broken time sync, and incomplete audit settings all reduce detection quality. If the underlying telemetry is unreliable, tuning the rule alone will not solve the problem.
Rules also age badly when nobody reviews them. Attack techniques change, business systems change, and platform schemas change. A quarterly review cycle is a sensible minimum for most SMEs, with ad hoc review after major changes. Retire rules that no longer match the environment.
Finally, avoid overfitting. A detection that only matches one known sample or one exact command line will miss simple variations. Focus on behavioural patterns and supporting context rather than brittle strings wherever possible.
A practical starting point for UK SMEs
If you are starting from a low baseline, do not try to cover everything at once. Pick a small number of detections that reflect your highest-risk attack paths and your best telemetry. For many SMEs, that means identity abuse, suspicious admin activity, endpoint execution anomalies, and a small set of network indicators.
A sensible first wave might include:
1. Suspicious sign-ins with impossible travel, unfamiliar devices, or risky authentication patterns.
2. Privilege escalation or new administrator creation in identity systems.
3. Suspicious process creation, script execution, or encoded command use on endpoints.
4. Lateral movement indicators such as remote service creation or unusual remote execution.
5. Network beaconing or unusual outbound connections from critical hosts.
Each of these should have a named owner, a documented hypothesis, and a validation plan. Once the first wave is stable, expand into more specific techniques based on your threat model and incident history.
From there, build a repeatable improvement loop. Review incidents and near misses, identify what was missed or noisy, update the detection backlog, validate changes, and measure the effect on analyst workload. That is how detection engineering becomes a sustainable capability rather than a collection of rules.
If you want help turning this into a practical operating model for your environment, we can support with advisory work that fits an ISO 27001-aligned approach and stays focused on what is realistic for a UK SME. Speak to a consultant if you would like to discuss your current detection posture and where to start.
Frequently asked questions
What is detection engineering in a SOC?
Detection engineering is the process of turning threat hypotheses and available telemetry into reliable alerts, then validating and maintaining those alerts over time. It sits between threat modelling, SIEM content development, and SOC operations.
How do you measure whether a detection is any good?
A useful detection has acceptable false positives, catches the intended behaviour, arrives quickly enough to support response, and does not create disproportionate maintenance effort. In practice, fidelity, latency, coverage, and operational cost are the most useful measures.
Comments are closed