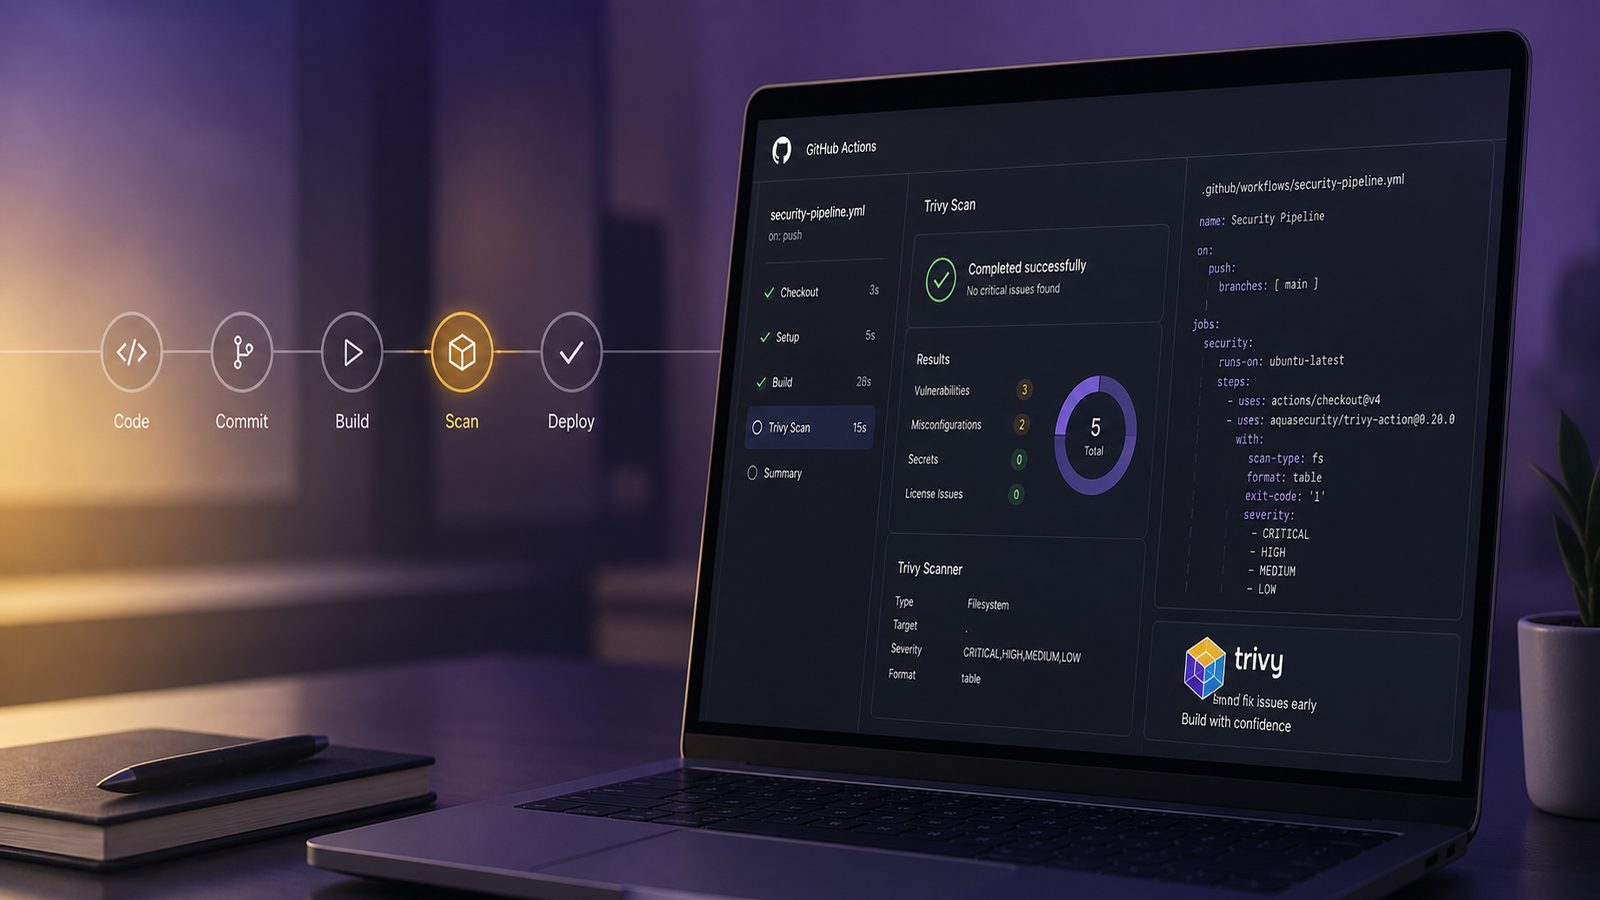
For UK SMEs building software, the question is rarely whether to add security scanning to CI. It is how to do it in a way that improves assurance without turning every pull request into noise. Trivy is a useful fit because it can scan container images, source repositories, infrastructure as code, secrets, and software bills of materials from a single toolchain. That makes it a practical control for teams that want broad coverage without stitching together too many separate scanners.
In a GitHub Actions pipeline, Trivy is most effective when it is treated as part of a wider secure delivery pattern rather than as a standalone gate. It complements SAST, DAST, and dependency scanning, but it does not replace them. If you already have a broader programme for secure delivery, this fits neatly alongside the work described in embedding security into CI/CD pipelines without slowing teams and hardening GitHub Actions against pwn requests and token theft.
Key takeaways
- Start with one repository and one scan mode so you can tune Trivy before expanding coverage.
- Use pull request feedback for developers and main branch gates for release assurance, but do not block every low severity finding.
- Pin Trivy versions, limit GitHub token permissions, and separate trusted from untrusted workflow paths.
- Treat ignore rules as temporary risk decisions with owners and review dates, not as a permanent fix.
- Pair Trivy findings with SBOM output and a clear remediation workflow so results lead to action.
Why Trivy fits into a GitHub Actions security pipeline
Trivy is an open source scanner from Aqua Security that checks for known vulnerabilities in operating system packages and application dependencies, common misconfigurations in files such as Kubernetes manifests and Terraform, exposed secrets, and SBOM output. For many teams, the value is not just the breadth of checks but the consistency of output. One tool can produce repeatable results across code, images, and deployment artefacts.
That breadth matters because modern delivery pipelines are rarely limited to one asset type. A repository may contain application code, Dockerfiles, Helm charts, Terraform, and workflow files. If you only scan the final container image, you may miss insecure defaults in the deployment layer. If you only scan source code, you may miss vulnerable base images or package layers. Trivy helps close that gap.
Used well, it also supports supply chain assurance. A scan result can be paired with an SBOM to show what is present in a build, which is helpful for remediation planning and for supplier conversations. If you are building a wider assurance model, it is worth reading implementing software supply chain assurance controls for technical teams alongside this guide.
What Trivy scans: vulnerabilities, misconfigurations, secrets, and SBOMs
Trivy has four practical uses in CI. First, vulnerability scanning against images and file systems. Second, misconfiguration scanning for infrastructure and deployment files. Third, secret detection to catch accidental commits of credentials. Fourth, SBOM generation, typically in SPDX or CycloneDX formats, for inventory and downstream review.
For technical teams, the important point is that these are separate control objectives. Vulnerability scanning is about known weaknesses in packages and libraries. Misconfiguration scanning is about insecure settings. Secret detection is about credential exposure. SBOM generation is about visibility and traceability. Keeping those objectives distinct makes it easier to tune thresholds and assign ownership.
Where Trivy sits alongside SAST, DAST, and dependency scanning
Trivy is best placed as a fast, automated control in the build and validation stages. It is not a substitute for source code review, threat modelling, or targeted security testing. Think of it as a control that catches common issues early and cheaply, before they reach later stages where fixes are more expensive.
In practice, many teams use Trivy for dependency and image scanning, a separate SAST tool for code-level issues, and DAST for runtime testing of deployed applications. That division of labour keeps each tool focused and reduces duplicate findings. It also makes it easier to map controls to frameworks such as OWASP SAMM or Microsoft SDL practices without overengineering the pipeline.
Planning the workflow before you add the scanner
Before writing the workflow file, decide what you want Trivy to protect and where it should run. A common mistake is to add scanning everywhere at once. That usually creates too much output, too many exceptions, and little operational value. Start with the repositories and branches that carry the highest delivery risk or the most sensitive code.
For UK SMEs, a sensible first step is to scan pull requests and main branch builds in one application repository. Pull request scans give developers early feedback. Main branch scans provide a cleaner signal for release readiness. If you build and publish container images, scan the image after it is built but before it is pushed to a registry or promoted to production.
Choosing which repositories, branches, and pull requests to scan
Not every repository needs the same level of scanning. Production services, build pipelines, and repositories containing deployment manifests should be first priority. Internal tools, prototypes, and documentation repositories may only need lighter scanning or no scanning at all, depending on the risk profile.
Branch strategy matters too. If your team uses feature branches and pull requests, run Trivy on pull requests for fast feedback, then run a fuller scan on merges to main. If you use trunk-based development, a single main branch scan may be enough, provided it runs on every change and the results are visible to the right people.
Defining what should fail the build and what should only warn
Not every finding should block delivery. That is one of the most important design decisions. A build gate should usually fail only on issues that are both high confidence and high impact, such as critical vulnerabilities in production images, or clearly insecure misconfigurations in deployment artefacts. Lower severity findings can be reported as warnings or routed into backlog items.
The right threshold depends on your risk appetite and release cadence. If you are early in the journey, start with reporting only, then move to blocking on a narrow set of conditions once you understand the baseline. This avoids turning the scanner into a source of friction before the team trusts the data.
Setting up Trivy in GitHub Actions
There are two common ways to use Trivy in GitHub Actions. You can use the official action, which is convenient for quick adoption, or install the Trivy CLI in a job if you want more control over versioning and command-line flags. For most SMEs, the action is the fastest route to value, but the CLI gives more flexibility when you need consistent behaviour across jobs.
Whichever route you choose, pin versions. Do not rely on floating tags for security tooling in a production pipeline. A scanner update can change detection logic, output format, or exit behaviour. Pinning reduces surprises and makes pipeline behaviour easier to reproduce.
Using the official Trivy action or installing the CLI in a job
A simple pattern is to run Trivy in a dedicated job after checkout and build steps. For example, you might scan a container image using the action, then publish the results as an artefact or annotate the pull request. If you prefer the CLI, install it with a package manager or direct binary download, then call it with explicit arguments.
A typical image scan command looks like this:
trivy image --severity HIGH,CRITICAL --exit-code 1 --format sarif --output trivy-results.sarif my-image:tag
For repository scanning, you might use:
trivy fs --scanners vuln,misconfig,secret --severity HIGH,CRITICAL --exit-code 1 .
These examples are intentionally conservative. They focus on the findings most likely to matter in a CI gate while still allowing you to collect broader data for review.
Pinning versions and controlling update behaviour
Trivy relies on vulnerability databases and misconfiguration rules. That means update behaviour needs thought. If the database updates during a build, results can change between runs even when the code has not changed. That is useful for freshness, but it can also make troubleshooting harder.
A common pattern is to update the database on a schedule, then use that cached state during normal pull request runs. In GitHub Actions, this can be done with caching or with a separate scheduled workflow that refreshes the database. The aim is to keep developer feedback fast while ensuring the scanner is not working from stale data for too long.
Scanning container images, source repositories, and infrastructure files
Different scan modes answer different questions. Image scanning tells you what is inside the built artefact. Repository scanning tells you what is present in the source tree. Misconfiguration scanning tells you whether the configuration is likely to create exposure when deployed. A mature pipeline usually uses more than one mode.
Image scanning for known vulnerabilities in base layers and packages
Image scanning is often the most immediately useful control because it catches vulnerable packages in base images and application layers. This is especially relevant where teams inherit images from upstream registries or use language runtimes that pull in many transitive packages.
For image scans, keep the scope focused on the images that are actually promoted. Scanning every intermediate build artefact can create unnecessary noise. If you build multiple images in one workflow, scan only the ones that are candidates for release or deployment.
It is also worth combining image scanning with image signing and provenance controls. Trivy tells you what is vulnerable. Signing tells you what was built and by whom. Those controls reinforce each other and fit well with a broader supply chain posture.
Misconfiguration scanning for Kubernetes, Terraform, and other IaC files
Misconfiguration scanning is where Trivy can catch issues that are easy to miss in code review. Examples include publicly exposed services, overly permissive security groups, missing resource limits, insecure TLS settings, and weak Kubernetes pod security settings. These are not theoretical issues. They are the sort of defaults that can slip into infrastructure as code when teams are moving quickly.
For Terraform, Kubernetes YAML, Helm charts, and similar files, run Trivy against the repository path or the rendered manifests. If you use generated manifests, scan the output that will actually be deployed rather than only the template source. That gives a more accurate view of the final risk.
If you already use other infrastructure scanners, Trivy can still add value by providing a second opinion or by covering file types that are not well handled elsewhere. It should not be used to duplicate every control, but it can provide useful breadth.
Tuning results so the pipeline stays usable
Security scanning only works when people trust it. If the pipeline is full of low-value findings, developers will start to ignore it. Tuning is therefore not a nice-to-have. It is part of the control design.
Severity thresholds, exit codes, and ignore rules
Trivy supports severity filtering and exit codes, which makes it straightforward to decide what blocks a build. A common pattern is to fail only on HIGH and CRITICAL findings in release branches, while allowing lower severities to pass with a warning. For early adoption, you may want to report all severities but only fail on a narrow subset.
Ignore rules should be used carefully. They are appropriate where a finding is understood, accepted, and tracked, such as a vulnerability in a package that cannot be updated immediately because of compatibility constraints. They are not a substitute for remediation. Keep ignore files small, reviewed, and time-bound where possible.
Reducing noise from false positives and accepted risk
False positives happen in every scanner. The practical response is to build a triage process, not to disable the tool. If a finding is repeatedly noisy, verify whether it is a genuine issue, a duplicate, or a result of how the artefact is built. Sometimes the answer is to adjust the scan target or the file path. Sometimes it is to suppress a specific rule with justification.
Accepted risk should be visible outside the workflow. If a team decides not to fix a finding immediately, that decision should be recorded in a ticket or risk register with an owner and review date. That keeps the pipeline honest and prevents ignore lists from becoming permanent blind spots.
Handling secrets and supply chain signals in the same workflow
One reason Trivy is attractive is that it can support multiple security objectives in one workflow. That said, it is still important to avoid overloading the pipeline. Secret scanning, vulnerability scanning, and SBOM generation can all run in the same job, but they should be staged so that the output remains readable.
Adding secret detection without overloading the pipeline
Secret detection is useful because accidental credential exposure is often a high-impact mistake. In GitHub Actions, it is sensible to run secret scanning on pull requests and on main branch merges, especially in repositories where developers regularly handle configuration files, scripts, or infrastructure definitions.
Do not rely on secret scanning alone. It is a backstop, not a substitute for good secret management. Use repository protections, environment secrets, and least privilege access in the workflow itself. If you want a broader view of the control area, see preventing secret leakage in CI/CD environments.
Generating SBOM output for downstream review and inventory
SBOM generation is often overlooked in CI, but it is valuable for inventory and incident response. If you can quickly identify what components were present in a build, you can assess exposure more efficiently when a new vulnerability is disclosed. Trivy can output SBOMs in common formats that can be archived as build artefacts or fed into downstream tooling.
For SMEs, the practical use case is simple. Keep an SBOM for each release artefact, store it alongside the build metadata, and make sure the team knows where to find it. That is usually enough to make the output useful without creating a separate governance project.
Hardening the GitHub Actions workflow itself
Security scanning is only one part of the control surface. The workflow that runs Trivy also needs hardening. If an attacker can influence the workflow, they may be able to exfiltrate tokens, tamper with results, or abuse the build environment.
Permissions, token scope, and least-privilege job design
Use the minimum GitHub token permissions required for the job. If the scanner only needs to read the repository and upload an artefact, do not grant write access. Split jobs where necessary so that the scan job cannot also publish releases or modify repository state.
It is also sensible to isolate jobs that handle untrusted pull requests from jobs that have access to secrets. If you need to scan pull requests from forks, use a design that avoids exposing sensitive tokens to that context. This is a core part of workflow hardening and should be treated as such, not as an optional refinement.
Protecting against untrusted pull requests and workflow abuse
Untrusted pull requests are a common source of CI abuse. Keep the workflow simple, avoid unnecessary shell interpolation, and be careful about any step that processes attacker-controlled input. If you are running Trivy on pull request content, ensure the job does not have access to privileged credentials unless there is a strong reason and a compensating control.
For teams that want to go further, consider using separate workflows for validation and release, with different permissions and different secrets. That separation reduces the blast radius if one workflow is manipulated.
Operationalising Trivy findings
A scanner only adds value when findings are acted on. The output should therefore be routed into the places where developers and platform engineers already work, such as pull request checks, logs, artefacts, and ticketing systems.
Routing results into pull request checks, logs, and ticketing
For day-to-day use, pull request annotations are the most effective feedback mechanism. They show the issue close to the change that introduced it. For broader visibility, store the raw output as an artefact and send a summary to your ticketing system or chat channel.
If you already have a vulnerability management process, map Trivy findings into that workflow rather than creating a separate queue. That keeps ownership clear. Application teams should own code and dependency issues. Platform teams should own base image and deployment configuration issues. Shared ownership is fine, but it should be explicit.
Setting a remediation workflow for developers and platform teams
Remediation works best when there is a predictable path. For example, a developer fixes application dependency issues in the next sprint, while a platform engineer updates base images or Terraform modules on a scheduled cadence. High severity issues should have a faster route, but the process should still be clear and repeatable.
It is also worth defining what happens when a finding cannot be fixed immediately. In that case, document the reason, the compensating control, and the review date. That keeps the decision visible and prevents temporary exceptions from becoming permanent exceptions.
Common implementation pitfalls
The most common mistake is to scan too late. If Trivy only runs after a merge or after an image is pushed to production, the feedback loop is too slow to be useful. Another common mistake is to treat every finding as a build blocker. That usually creates alert fatigue and encourages workarounds.
A better approach is to start with a narrow, high-value use case, tune the thresholds, and expand gradually. Keep the workflow readable. Keep the ownership clear. Keep the output actionable.
A practical rollout approach for UK SMEs
For a small team, the best rollout is usually incremental. Start with one repository, one scan type, and one branch policy. For example, scan the main application repository on pull requests for secrets and misconfigurations, then add image scanning once the team is comfortable with the baseline. After that, extend the pattern to other services.
Once the first pipeline is stable, add reporting and retention. Keep artefacts for a sensible period, review the findings trend over time, and use that data to refine your thresholds. This is where the control starts to support management reporting as well as engineering hygiene.
If you want to align the work to a broader secure development maturity model, Trivy can sit within an OWASP SAMM or Microsoft SDL style programme as a repeatable verification step. It is not the whole programme, but it is a practical and defensible part of it.
For SMEs that want help designing the workflow, tuning the gates, or aligning the control to a wider assurance approach, Speak to a consultant.
Frequently asked questions
Should Trivy run on pull requests, merges to main, or both?
Both is usually the best pattern. Pull request scans give fast developer feedback, while main branch scans provide a cleaner release control and help catch issues that only appear after merge or build.
Can Trivy replace other security testing tools?
No. Trivy is useful for vulnerability, misconfiguration, secret, and SBOM checks, but it should sit alongside SAST, DAST, threat modelling, and code review rather than replacing them.
How do you balance scan coverage with build speed and false positives?
Start with the highest value repositories and the most relevant scan types, then fail only on a narrow severity threshold. Keep the rest as warnings until you have a stable baseline and a triage process.
Comments are closed