
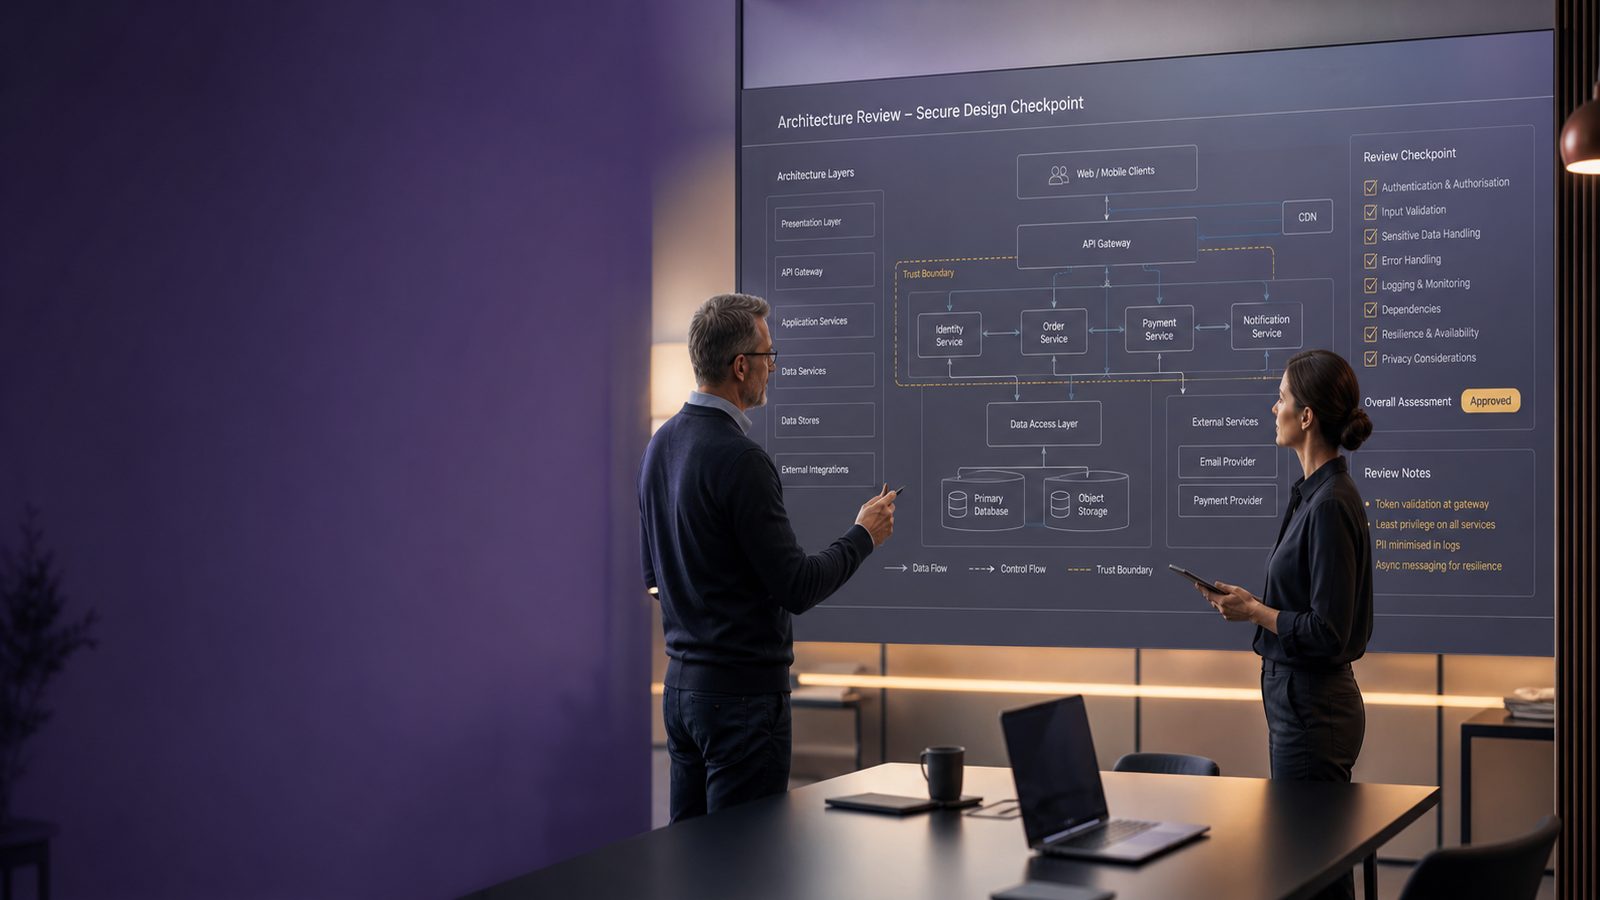
Secure design reviews and architecture checkpoints in the SDLC
For many UK SMEs, security work becomes most effective when it is built into the way software is designed and delivered, rather than added at the end. A secure design review is one of the most useful points in the software development lifecycle (SDLC) to catch structural weaknesses before they become expensive to fix. An architecture checkpoint is the practical version of that idea: a structured review of the design, the assumptions behind it, and the controls needed to make it safe to operate.
This matters because some of the most damaging issues are not code defects in the narrow sense. They are design problems. Examples include weak trust boundaries, over-privileged service accounts, unclear data handling, fragile dependencies, poor failure handling, and logging that cannot support investigation. These issues are often invisible in unit tests and may not be obvious in a code review until the system is already in production.
For technical teams, the goal is not bureaucracy. It is to create a lightweight decision point that improves design quality, reduces rework, and gives the business a clearer view of risk. If you already use threat modelling, architecture governance, or DevSecOps practices, the checkpoint should complement them rather than duplicate them. A useful reference point is the broader secure development guidance in our article on secure software development, which sets the context for why these reviews belong early in delivery.
Why design reviews matter in secure software delivery
Where design reviews sit in the SDLC
The best time to review a design is after the team has enough detail to reason about the system, but before implementation has hardened the architecture. In practice, that usually means after the high-level requirements and initial solution shape are known, and before major build work starts. At this stage, the team can still change data flows, choose a different authentication pattern, split a service, or remove an unnecessary integration.
In an agile environment, this does not need to be a heavyweight stage gate. A checkpoint can happen when a feature epic, major change, or new service reaches a design-ready state. The key is to make it a normal part of delivery, not an exceptional event reserved for only the most sensitive projects.
What problems they catch that code review and testing miss
Code review is good at spotting implementation mistakes. Testing is good at validating behaviour. Neither is ideal for identifying whether the architecture itself is safe. A design review can catch issues such as:
- data being sent to a third party without a clear business need
- authentication being handled differently across services, creating inconsistent trust
- an API exposing more data than the front end actually uses
- shared secrets being reused across environments
- failure states that cause insecure fallback behaviour
- dependencies that introduce unacceptable operational or supply chain risk
These are the kinds of issues that often survive into production because the implementation is technically correct, but the design is weak. That is why architecture checkpoints are most valuable when they are used to challenge assumptions, not just to approve diagrams.
What a useful architecture checkpoint should cover
Trust boundaries, data flows, and abuse cases
Start with the system context. A good checkpoint should show where data enters the system, where it moves, where it is stored, and where it leaves. Data-flow diagrams are useful here because they force the team to be explicit about trust boundaries. If you need a refresher on that technique, our article on applying data-flow diagrams to security threat modelling is a useful companion.
For each boundary, ask what is trusted, what is not trusted, and what assumptions are being made. Then test those assumptions with abuse cases. An abuse case is simply a misuse scenario from an attacker or failure perspective. For example, what happens if an unauthenticated user reaches an internal endpoint, if a partner integration sends malformed data, or if a queue backs up and the system starts dropping validation steps?
In a technical review, this is where STRIDE, attack trees, or similar threat modelling methods can help structure the discussion. The checkpoint should not become a theoretical exercise. It should identify concrete design changes, such as adding validation at a trust boundary, isolating a sensitive service, or changing a data retention decision.
Identity, secrets, dependencies, and external services
Identity is often the first control plane to review. Check how users, services, and administrators authenticate and authorise access. Look for over-broad RBAC, shared service identities, long-lived tokens, and unclear separation between human and machine access. If the design depends on a central identity provider, confirm what happens if that service is unavailable and whether the system fails closed where appropriate.
Secrets deserve the same level of attention. Review where API keys, certificates, signing material, and database credentials are stored, rotated, and accessed. Hard-coded secrets, environment-variable sprawl, and shared credentials across environments are all signs that the design needs work. A separate control discussion may be needed for key management, but the checkpoint should at least confirm the intended pattern.
Dependencies and external services should be treated as part of the architecture, not as implementation detail. That includes open source packages, SaaS integrations, managed cloud services, and third-party APIs. Ask what the dependency does, how it is updated, what telemetry is available, and what the fallback looks like if it fails. For a broader view of this risk area, see our article on how third-party software introduces cyber risk for UK SMEs.
How to structure the review process for a growing team
Lightweight review gates for agile delivery
SMEs usually need a process that is simple enough to run consistently. A practical pattern is to define three checkpoints:
- concept review, when the team is still shaping the solution
- design review, when the main components and data flows are known
- pre-release review, when the implementation is close to production
Each checkpoint should have a clear purpose. The concept review should decide whether the proposed approach is sensible from a security perspective. The design review should test the architecture and identify required controls. The pre-release review should confirm that the agreed controls have actually been implemented and that any residual risk is understood.
Keep the gate criteria short. If the team needs a 20-page checklist to pass the review, it will be bypassed. A better approach is to define a small set of mandatory artefacts and questions, then allow the depth of review to scale with risk.
Who should attend and what evidence to capture
For most SMEs, the review should include the product owner or delivery lead, a developer or engineer who understands the implementation, someone responsible for security or architecture, and, where relevant, operations or platform support. If the system touches regulated data, customer-facing APIs, or critical business processes, include the relevant business owner too.
The evidence captured should be enough to show what was reviewed and what was decided. That usually means:
- a versioned architecture diagram
- the data-flow view
- key assumptions and dependencies
- identified risks and agreed actions
- the decision, including any exceptions
Do not overcomplicate the record. A short review note in the ticketing system or architecture repository is often enough if it is consistent and traceable. The important thing is that future teams can understand why a design was accepted or changed.
Practical review criteria for technical teams
Security requirements, threat modelling, and control selection
Every checkpoint should start with the security requirements for the system. These may come from customer commitments, internal policy, data classification, or product risk appetite. The review should confirm that the design actually supports those requirements. If the system handles personal data, payment data, or privileged administrative actions, the design should reflect that from the outset.
Threat modelling should be used to select controls, not as a separate academic exercise. Once the team has identified plausible threats, map them to design responses. For example:
- if spoofing is a concern, review authentication strength and token handling
- if tampering is a concern, review integrity checks and signing
- if information disclosure is a concern, review encryption, access control, and logging hygiene
- if denial of service is a concern, review rate limiting, queue design, and graceful degradation
Frameworks such as OWASP ASVS can help turn these ideas into concrete application controls, especially for web-facing systems. The checkpoint is the place to decide which control depth is appropriate for the risk.
Logging, monitoring, resilience, and failure modes
Security design is incomplete if it ignores operations. The review should ask what will be logged, where logs will go, and whether the logs will be useful for detection and investigation. It should also check whether sensitive data is excluded from logs, whether timestamps are consistent, and whether the system emits enough context to reconstruct events.
Resilience is equally important. A design that is secure only when everything works perfectly is not robust. Review failure modes such as expired tokens, unavailable dependencies, partial outages, and delayed background jobs. Decide whether the system should fail closed, fail open, or degrade gracefully in each case. This is especially important for customer-facing services and internal platforms that support business-critical workflows.
If the checkpoint identifies a single point of failure, treat it as a design issue rather than an operational inconvenience. Our article on identifying bottlenecks and single points of failure in security architecture goes deeper into that topic.
Common anti-patterns to avoid
Treating the review as a one-off sign-off
One of the most common mistakes is to treat the review as a box-ticking exercise. A design that was acceptable at concept stage may become risky once the implementation changes, a new dependency is added, or the scope expands. If the checkpoint is only ever used as a sign-off, it will miss those shifts.
Instead, treat it as a living control. Revisit the design when the architecture changes materially, when new data types are introduced, or when the team discovers that the original assumptions were wrong. This is more realistic for SMEs than trying to predict every issue up front.
Reviewing diagrams without operational context
Another anti-pattern is reviewing a diagram in isolation. A neat architecture picture can hide a great deal of risk if the team does not understand deployment, identity, logging, or support processes. A service may look secure on paper but still be fragile if it depends on manual secret rotation, undocumented admin access, or a brittle release process.
To avoid this, ask how the system will actually be run. Who will patch it? Who can access production? How are secrets rotated? What happens during incident response? What is the rollback plan? These questions often reveal the real security posture more clearly than the diagram itself.
Making checkpoints work with DevSecOps
Linking reviews to backlog items and release criteria
In a DevSecOps environment, the checkpoint should be connected to the delivery workflow. Findings should become backlog items with owners and due dates. If a risk is accepted, the acceptance should be recorded with the rationale and review date. If a control is required before release, it should be part of the release criteria rather than an informal promise.
This makes the process easier to manage and easier to evidence. It also helps product and engineering teams see security work as part of delivery, not as a separate stream that appears late in the project.
Using automation to support, not replace, human judgement
Automation can improve the quality of the checkpoint, but it cannot replace judgement. Static analysis, dependency scanning, infrastructure-as-code checks, and policy-as-code rules can all provide useful signals. They can also reduce the chance that obvious issues are missed. But they cannot tell you whether a proposed architecture makes sense for the business, whether a trust boundary is appropriate, or whether a failure mode is acceptable.
Use automation to gather evidence before the review. For example, a pipeline might attach SAST results, dependency reports, container scan output, or infrastructure diffs to the design ticket. The human review then focuses on the decisions that require context. That balance is usually the most effective approach for smaller teams.
How to measure whether the process is effective
Lead indicators and quality measures
Do not measure success only by the number of reviews completed. That tells you very little. Better measures include:
- the proportion of significant changes that were reviewed before build work started
- the number of design issues found before implementation versus after release
- the time taken to close review actions
- the number of recurring issues, such as weak logging or poor secret handling
- the percentage of reviews that resulted in a meaningful design change
These measures show whether the checkpoint is influencing design quality. If the same issues keep appearing, the process may be too shallow or the architecture standards may need to be improved.
Using findings to improve architecture standards
Over time, review findings should feed back into reusable standards. If the team repeatedly sees the same problems, turn them into reference patterns, approved design templates, or minimum control requirements. That might include standard authentication flows, logging baselines, secrets handling patterns, or dependency approval criteria.
This is where the checkpoint becomes more than a review. It becomes part of organisational learning. The result is a more consistent architecture posture and less reliance on individual memory.
When to revisit a design after release
Triggers for re-review after major changes
Post-release review is important when the system changes in ways that affect risk. Common triggers include:
- new data categories or higher sensitivity data
- new integrations or third-party services
- changes to authentication, authorisation, or identity provider design
- major infrastructure changes, such as cloud migration or tenancy changes
- significant incident findings or repeated operational failures
- material changes to threat landscape or business usage
When one of these triggers appears, the team should re-check the assumptions made in the original design review. In many cases, a short targeted review is enough. The point is to avoid letting an old design decision silently govern a new risk profile.
Handling exceptions and risk acceptance
Sometimes the right answer is not to fix everything immediately. An SME may need to accept a risk temporarily because of delivery constraints, customer commitments, or technical debt. That can be reasonable, provided the exception is explicit, time-bound, and owned by someone with the right authority.
Risk acceptance should include the issue, the reason it is being accepted, the compensating controls in place, and the review date. It should not be a vague note in a meeting. If the exception is likely to remain in place for a long time, it should be visible in the architecture record and tracked like any other material risk.
Secure design reviews and architecture checkpoints work best when they are practical, repeatable, and tied to real delivery decisions. For UK SMEs, that usually means keeping the process light enough to use, but structured enough to influence the design before it is too late to change. If you want help shaping a review process that fits your delivery model, a consultant can help you define the right checkpoints, evidence, and control expectations without adding unnecessary overhead.
For a wider discussion about how architecture, governance, and secure development fit together, you may also find our article on applying TOGAF for security architecture design useful.
For organisations looking to strengthen their secure development approach in a way that is proportionate to size and risk, this is also a natural place to align architecture reviews with your wider information security management system and delivery governance.
Speak to a consultant if you would like practical support designing a review process that fits your team, your delivery cadence, and your risk profile.
Frequently asked questions
How is a design review different from threat modelling?
Threat modelling is a technique for identifying threats, trust boundaries, and likely abuse paths. A design review is the broader decision point where the team checks whether the overall architecture is acceptable, whether the right controls have been selected, and whether the design is operationally workable. In practice, threat modelling is often one input to the design review.
What evidence should we keep from an architecture checkpoint?
Keep enough to show what was reviewed, what risks were identified, what decisions were made, and who approved them. A versioned diagram, a short summary of assumptions, the key findings, the action list, and any recorded exceptions are usually sufficient. The record should be easy to find later and clear enough for another engineer or architect to understand.
How often should we run architecture checkpoints?
Run them whenever a change is large enough to affect trust boundaries, data handling, identity, dependencies, or failure modes. For many SMEs, that means at concept stage for new work, again before build is too far advanced, and once more before release if the design has changed materially.
Do small teams really need a formal review process?
Yes, but it should be proportionate. Small teams often have less separation of duties and fewer people to catch design issues informally. A simple, repeatable checkpoint can improve consistency without creating unnecessary process overhead.
Comments are closed