
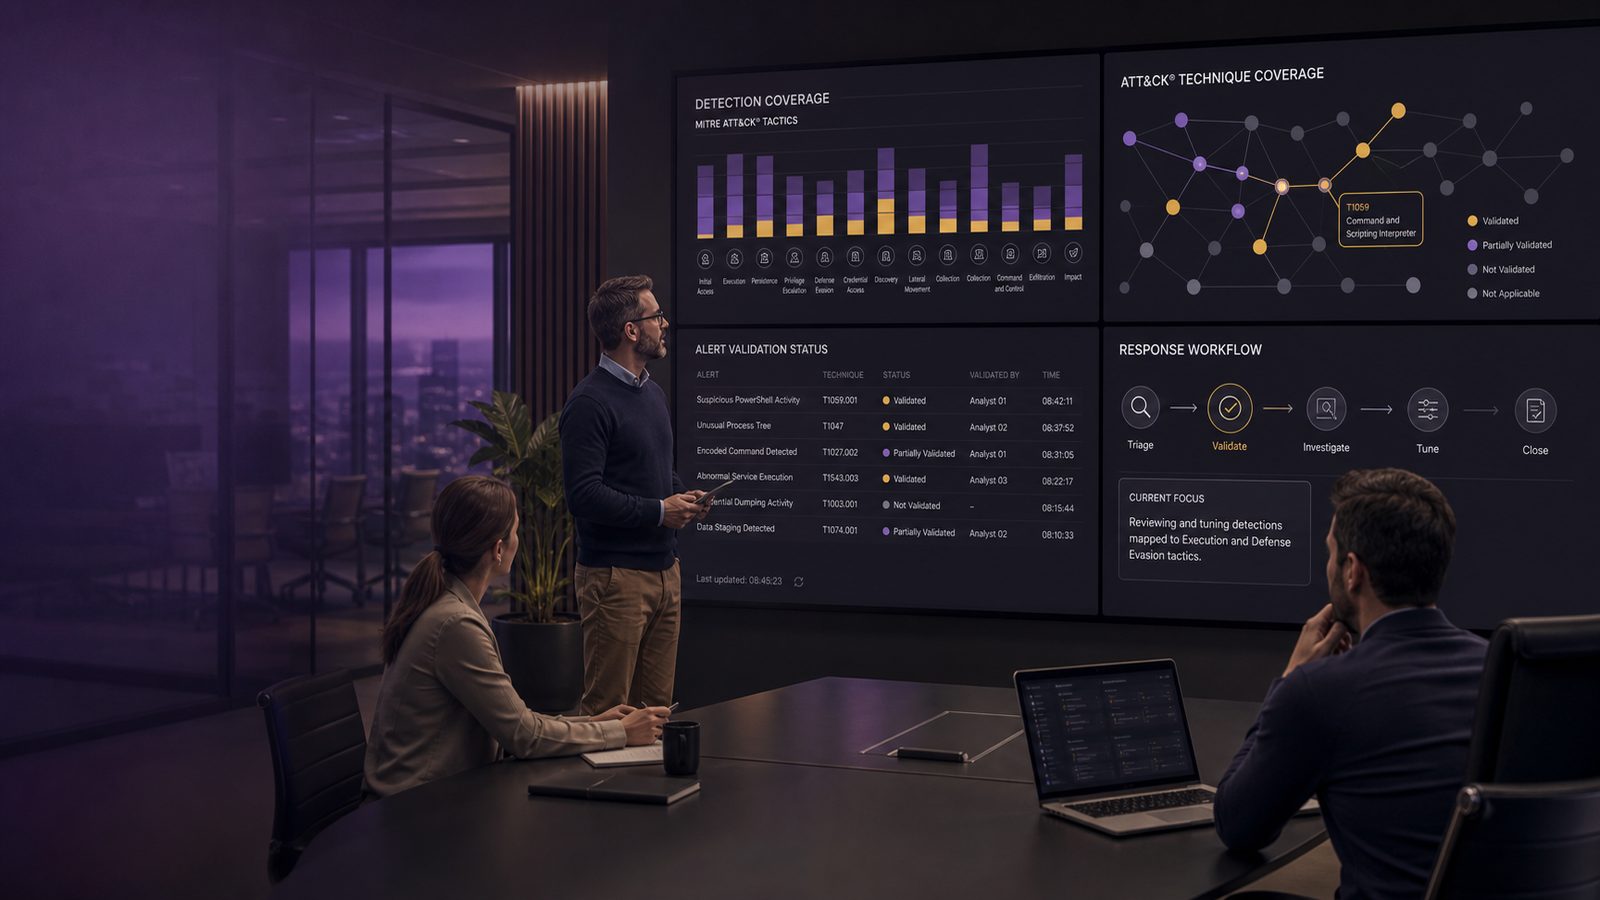
Purple-team validation is the practical bridge between a threat model and a detection that actually works in production. For UK SMEs, it is one of the most useful ways to answer a simple question: if an attacker uses a known technique, will we see it, will the alert be useful, and will the team respond in time?
The value is not in proving that a control exists on paper. It is in testing whether telemetry is present, whether the logic in the SIEM or XDR platform fires with the right fidelity, and whether analysts can triage the event without wasting time on noise. That is why purple-team validation of detections against MITRE ATT&CK is best treated as an operational exercise, not a one-off test.
MITRE ATT&CK gives you a common language for describing adversary behaviour. It helps security engineers, SOC analysts, and incident responders agree on what is being tested, what evidence should appear, and what a pass or fail looks like. If you already map detections to ATT&CK, as discussed in our practical guide to mapping detections and controls to MITRE ATT&CK, purple-team validation is the next step: prove that the mapping holds under controlled execution.
Key takeaways
- Purple-team validation should prove that telemetry, detection logic, and analyst response all work in practice.
- Start with a small set of ATT&CK techniques that match your most likely adversary paths and most important assets.
- Define clear pass, partial pass, and fail outcomes so you can tune logging, rules, and runbooks with precision.
- Measure alert quality and triage time, not just whether an alert appeared.
- Feed findings into detection-as-code, playbooks, and retesting so improvements are sustained.
What purple-team validation is and where it fits
In a traditional red team exercise, the focus is on achieving objectives while staying as realistic as possible. In a detection engineering workflow, the focus is on building logic, tuning alerts, and improving telemetry. Purple teaming sits between the two. It is collaborative, controlled, and designed to improve visibility rather than to surprise the defenders.
That distinction matters. A purple-team exercise should not be judged by whether the tester “got in”. It should be judged by whether the organisation can observe the behaviour, understand the alert, and respond appropriately. In practice, that means the test is usually planned with the SOC, the platform owner, and the relevant system owner in advance.
ATT&CK is useful here because it breaks adversary activity into discrete techniques and sub-techniques. That lets you validate one behaviour at a time, such as suspicious PowerShell execution, remote service creation, or credential dumping indicators, rather than trying to simulate an entire intrusion in one go. The result is more actionable feedback for detection engineers and analysts.
How it differs from red teaming, detection engineering, and threat-led testing
Red teaming is often objective-led and adversary-emulation focused. Detection engineering is about writing and tuning the logic that turns telemetry into alerts. Threat-led testing uses intelligence about likely adversaries to prioritise scenarios. Purple-team validation borrows from all three, but its purpose is narrower: confirm that specific detections work in the environment you actually run.
For SMEs, that narrower scope is an advantage. It keeps the exercise affordable, reduces operational risk, and makes it easier to turn findings into improvements. It also avoids the common mistake of treating a large-scale exercise as proof that all detection gaps have been closed.
Why ATT&CK is useful as the common language for test cases
ATT&CK gives structure to the exercise. Each test case can be tied to a technique, a platform, an expected telemetry source, and a response path. That makes it easier to compare results over time and to explain findings to stakeholders who need a concise summary rather than a technical narrative.
It also helps with prioritisation. If your environment is mostly Microsoft-based, for example, you can focus on techniques that are realistic for your identity, endpoint, and cloud telemetry stack. If you have a small SOC, you can start with a handful of high-value techniques and expand as your detection maturity improves.
What good validation should prove
A useful validation programme should prove three things. First, that the telemetry exists. Second, that the detection logic fires with the right fidelity. Third, that the operational response is good enough for the business.
Whether the telemetry exists to see the behaviour
Many failed detections are really logging failures. If the endpoint does not emit the right process creation events, if identity logs are incomplete, or if network telemetry is too sparse, the detection cannot work reliably. Validation should therefore start with the question: what evidence should appear when this technique is executed?
For example, if you are validating a process-based technique, you may need command-line logging, parent-child process relationships, and user context. If you are validating identity abuse, you may need sign-in logs, audit logs, and conditional access events. If you are validating lateral movement, you may need endpoint, authentication, and network data together.
Whether the detection logic fires at the right fidelity
A detection that fires too late, too often, or on the wrong activity is not operationally useful. Validation should check whether the alert is specific enough to be actionable and broad enough to catch realistic variants. This is where rule quality matters as much as coverage.
For teams building detections in Sigma, KQL, or Splunk SPL, the test should confirm that field selection, filters, and correlation logic behave as intended. If you are using a detection-as-code workflow, the test should also confirm that the rule version deployed in the SIEM matches the version under review. Our article on building SIEM detections using Sigma rules is a useful companion if you want to connect validation with rule development.
Whether analysts can triage and respond within an acceptable window
Detection is only half the story. If the alert lands in the queue but the analyst cannot quickly understand what happened, the business still carries risk. Validation should therefore measure triage time, enrichment quality, and whether the escalation path is clear.
For SMEs, this is often where purple teaming produces the most value. A technically correct alert can still fail operationally if it lacks context, points to the wrong host, or generates too many duplicates. The exercise should show whether the analyst can move from alert to action without unnecessary investigation overhead.
Selecting ATT&CK techniques to validate first
You do not need to validate the entire ATT&CK matrix to get value. Start with a small set of techniques that reflect your most likely adversary paths and your most important assets. For many UK SMEs, that means identity abuse, endpoint execution, privilege escalation, and lateral movement.
Prioritising by business-critical assets and likely adversary paths
Begin with the systems that matter most to the business: identity providers, finance systems, customer data stores, remote access services, and admin workstations. Then ask which ATT&CK techniques are most plausible against those assets. A technique that is common in the wild and relevant to your environment is a better first candidate than an obscure technique that is unlikely to appear.
If you already have threat modelling or attack path analysis, use it. If you have recent incidents or near misses, use those too. Purple-team validation should be driven by risk, not by curiosity.
Using recent incidents, threat intelligence, and control gaps to choose techniques
Recent incidents often reveal where your detection gaps are. If you have seen suspicious authentication activity, validate identity-related techniques. If you have had endpoint alerts that were hard to triage, validate process and script-based techniques. If your threat intelligence suggests a likely ransomware path, focus on the stages that would give you early warning.
This is also where a technique-level exercise complements broader security testing. If you have already used Atomic Red Team for repeatable checks, you can reuse the same technique definitions as the basis for purple-team validation. The difference is that purple teaming adds collaboration, measurement, and tuning.
Building a safe validation scope
Safe scope design is essential. The aim is to validate detections without causing unnecessary disruption, triggering incident response confusion, or affecting production users. That means defining the environment, the accounts, the timing, and the rollback plan before any test begins.
Defining test accounts, hosts, time windows, and rollback steps
Use dedicated test accounts and, where possible, non-production hosts or isolated production-adjacent systems. If the technique requires a real production endpoint, choose a low-risk machine with the right telemetry enabled. Avoid using privileged accounts unless the test specifically requires privilege context and the risk has been agreed in advance.
Set a clear time window and make sure the SOC knows when the test will happen. Define rollback steps for any changes made during the exercise, including temporary policy exceptions, test artefacts, scheduled tasks, or service changes. If the test modifies configuration, document the exact pre-test state so it can be restored cleanly.
Coordinating with SOC, IT operations, and service owners
Purple teaming works best when the people who own the telemetry and the people who handle the alert are involved early. The SOC needs to know what to expect. IT operations need to know whether any endpoint, identity, or network control may be affected. Service owners need to understand whether the test could touch a business-critical application.
For SMEs with limited staff, this coordination can be lightweight, but it should still be explicit. A short test plan, a named contact for each team, and a clear stop condition are usually enough. If you are already using incident response runbooks, this is a good time to check whether they reflect the actual alerting workflow. Our guide to creating incident response playbooks and runbooks is relevant here.
Designing the test cases and success criteria
Each test case should be specific. A good test case states the ATT&CK technique, the target platform, the expected telemetry, the expected alert, and the expected analyst action. Without that structure, it becomes difficult to tell whether a failure is due to missing logs, weak logic, or poor response.
Mapping each test to an ATT&CK technique and expected telemetry
For example, a test case might validate a suspicious PowerShell execution pattern on Windows endpoints. The expected telemetry could include process creation events, script block logging, and the SIEM alert generated from a Sigma rule or KQL query. Another test could validate a remote service creation technique, with expected evidence in endpoint telemetry and authentication logs.
Keep the mapping simple enough that the team can maintain it. A spreadsheet or lightweight detection register is often enough for smaller environments. More mature teams may prefer a detection coverage platform or a structured repository that links ATT&CK techniques, rules, and test results.
Defining pass, partial pass, and fail outcomes
Not every result is binary. A pass means the telemetry appeared, the alert fired, and the analyst could triage it with confidence. A partial pass might mean the telemetry was present but the alert was too noisy, or the alert fired but lacked enough context. A fail means the behaviour was not visible, or the alert did not fire at all.
This distinction matters because partial passes often point to the most useful tuning work. For example, the detection may be technically correct but need better enrichment, a narrower threshold, or a suppression rule for known benign activity. That is more actionable than simply marking the control as “covered”.
Tools and approaches commonly used in practice
The tooling should fit the scope. You do not need a large orchestration platform to validate a handful of detections, but you do need repeatability and control.
Atomic Red Team for repeatable technique-level checks
Atomic Red Team is useful when you want a consistent, technique-level test that can be run safely and repeatedly. It helps standardise the behaviour under test and makes it easier to compare results across environments. If you want to understand the approach in more depth, see our article on simulating adversary techniques safely with Atomic Red Team.
For validation work, the key benefit is reproducibility. You can run the same atomic test after a rule change, after a logging change, or after a platform migration and compare the outcome.
Caldera, Prelude Operator, or similar orchestration for controlled campaigns
Where you need a sequence of techniques rather than a single check, orchestration tools can help. Platforms such as Caldera or Prelude Operator can coordinate a controlled campaign, making it easier to validate chained behaviours and the handoff between detections. That said, orchestration should not replace judgement. The test still needs a clear scope, a stop condition, and a human review of the results.
Sigma, KQL, and Splunk SPL for detection logic validation
Validation is most useful when it is close to the actual detection logic. If your rules are written in Sigma and translated into platform-specific queries, test the translated query as deployed. If you use Microsoft Sentinel, validate the KQL against the exact tables and fields in your workspace. If you use Splunk, test the SPL against the indexes and sourcetypes that your SOC actually queries.
This is also where detection engineering discipline helps. Version control, peer review, and test artefacts make it much easier to understand why a rule changed and whether the change improved fidelity.
What to measure during validation
If you do not measure the outcome, you will only know that something happened, not whether the detection capability improved. A good validation programme tracks both technical and operational metrics.
Alert generation, alert quality, and analyst handling time
At minimum, record whether the alert fired, how long it took to appear, whether it contained enough context, and how long it took the analyst to triage. If your SOC uses severity levels, note whether the alert was classified appropriately. This helps distinguish between a missed detection and a detection that was technically correct but operationally weak.
Coverage gaps, false negatives, and noisy detections
Coverage gaps are the most obvious outcome, but noisy detections are often just as important. A rule that fires too often will be ignored, which means the organisation still lacks effective detection. Track false positives, duplicate alerts, and cases where the same behaviour generated different outcomes across endpoints or users.
If you already measure detection quality, use the same metrics here. Our article on measuring detection quality and false positives is a useful reference point for deciding what “good” looks like in operational terms.
Evidence quality for later review and tuning
Keep enough evidence to reproduce the result. That usually means the test case, timestamps, affected host or account, the alert payload, relevant log excerpts, and the analyst notes. Without this, tuning becomes guesswork. With it, you can compare the before and after state and prove that the change improved the outcome.
How to tune detections after a failed or partial test
Most purple-team exercises uncover at least one gap. The value comes from turning that gap into a concrete improvement rather than treating it as a one-off finding.
Improving log sources and field selection
If the telemetry is missing, fix the logging first. That may mean enabling process creation logging, increasing audit coverage, forwarding additional identity events, or collecting the right cloud logs. If the telemetry exists but the detection cannot use it, check whether the required fields are being parsed and normalised correctly.
Field selection matters. A rule that relies on a noisy field or an inconsistent data source will be fragile. In many environments, the quickest improvement is not a more complex query but a better log pipeline.
Adjusting thresholds, correlation logic, and suppression rules
If the alert fired but was too noisy, tune the threshold or correlation logic. If a benign administrative action looks similar to the malicious pattern, consider scoped suppression based on device group, account type, or change window. The aim is not to hide activity, but to reduce predictable noise without creating blind spots.
Be careful with suppression. Every exception should be documented, time-bounded where possible, and reviewed regularly. Otherwise, temporary tuning becomes permanent risk.
Reducing blind spots without creating alert fatigue
The right balance is usually incremental. Improve one detection, validate it again, and then move to the next technique. This avoids the common trap of making broad changes that increase alert volume faster than the team can absorb it. For SMEs, sustainable improvement is usually better than ambitious but unmaintainable coverage.
Using results to improve wider security operations
Purple-team validation should feed into the wider security operating model. If it does not, the exercise becomes a report rather than a capability improvement.
Feeding findings into detection-as-code and CI/CD workflows
Where possible, treat detections like code. Store rules in version control, review changes, and test them before deployment. If a purple-team exercise reveals a gap, convert the fix into a tracked change and retest it. That creates a repeatable improvement loop and reduces dependence on tribal knowledge.
This approach also supports consistency across environments. If you have multiple tenants, business units, or log sources, detection-as-code helps keep the logic aligned while still allowing local differences where needed.
Updating playbooks, runbooks, and escalation paths
Validation findings should also update the human side of detection. If analysts needed extra context, add it to the alert enrichment. If the escalation path was unclear, update the runbook. If the SOC needed to contact IT operations to confirm a benign event, document that step so it happens faster next time.
That is especially important for smaller teams where one person may cover several roles. A clear runbook can save time and reduce uncertainty when an alert appears outside normal hours.
Tracking progress over time with coverage and quality metrics
Use a small set of metrics that the team can sustain. For example, track the number of ATT&CK techniques validated, the proportion that passed on first attempt, the average time to triage, and the number of detections improved as a result. Over time, those metrics show whether the programme is becoming more effective or just more active.
Coverage alone is not enough. A high coverage score with poor fidelity can still leave the business exposed. The better measure is whether the organisation can detect, understand, and respond to the techniques that matter most.
Common pitfalls in purple-team validation
There are a few recurring mistakes worth avoiding. The first is testing only easy techniques. That can create a false sense of confidence because the team validates what is already well covered and ignores the harder paths.
The second is treating ATT&CK coverage as a percentage target without context. A spreadsheet full of checked boxes does not mean the detections are useful. The third is ignoring operational constraints. If the test creates too much disruption, the business will stop supporting it, regardless of how technically interesting it is.
Another common issue is failing to close the loop. If the exercise identifies a gap but no one owns the fix, the same gap will still be there next quarter. The best programmes assign owners, deadlines, and retest dates.
How this supports a broader security programme
Purple-team validation is most effective when it sits inside a broader improvement cycle. It supports the Detect and Respond functions in NIST CSF by turning abstract capability statements into observable outcomes. It also gives useful evidence for risk treatment discussions because it shows where controls work, where they are weak, and where compensating measures may be needed.
For UK SMEs, that makes the exercise valuable even when resources are limited. You do not need a large team to benefit from it. You need a small number of realistic test cases, safe execution, honest measurement, and a willingness to tune the environment based on what you learn.
If you want help turning ATT&CK-mapped test cases into a practical validation plan, or aligning the findings with your wider security and ISMS work, speak to a consultant.
Frequently asked questions
How often should detections be validated against ATT&CK?
For most UK SMEs, a quarterly cadence works well for core detections, with additional validation after major changes such as SIEM migrations, logging changes, identity platform changes, or significant rule updates. High-risk techniques or critical assets may justify more frequent checks.
What is the difference between ATT&CK coverage and detection effectiveness?
ATT&CK coverage tells you whether a technique is mapped or theoretically monitored. Detection effectiveness tells you whether the organisation actually sees the behaviour, generates a useful alert, and can respond in time. Coverage is a starting point, not proof of operational success.
Comments are closed