
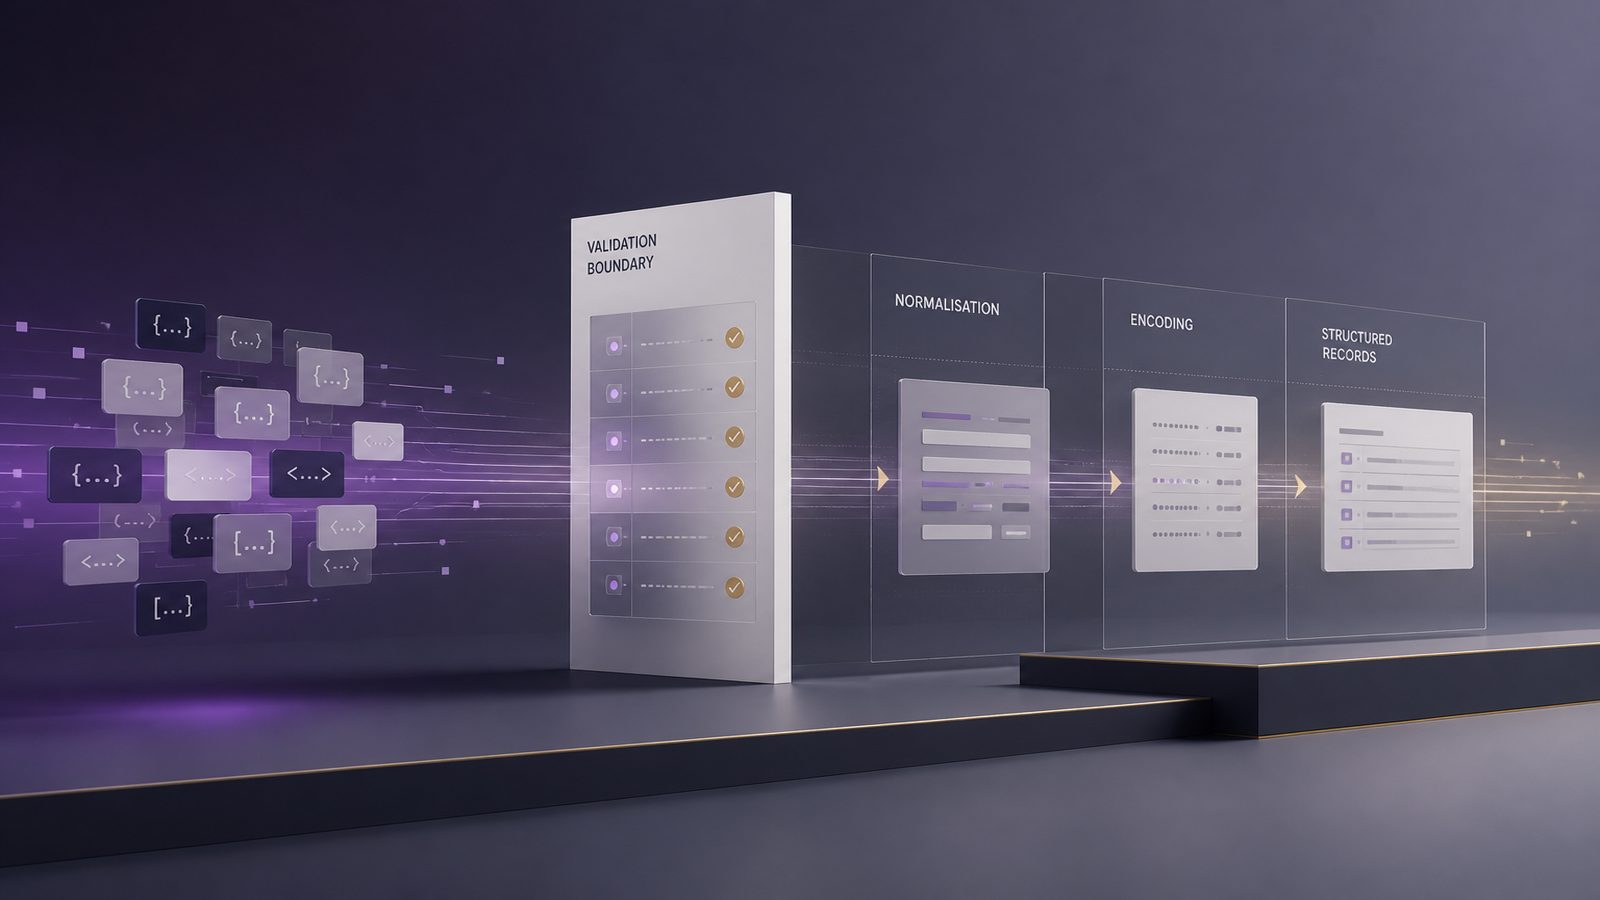
External data should be treated as hostile until it has been checked, constrained, and transformed for the specific place it will be used. That applies whether the data comes from a browser form, a mobile app, an API client, a file upload, an integration partner, or another internal service. In practice, many security issues start when a system assumes that input is already safe because it arrived over a trusted channel.
For technical teams, the useful mindset is simple: trust boundaries matter. Every boundary where data crosses from one component to another is a point where assumptions can break. If you design those boundaries carefully, you reduce the chance of injection flaws, parser abuse, broken workflows, and downstream failures. You also make the application easier to reason about, test, and monitor.
This article focuses on practical input validation and encoding strategies for UK SMEs building or operating web applications, APIs, and internal platforms. It is written for engineers and architects who need controls that work in real systems rather than in theory. If you want a broader view of how this fits into secure design, it can help to read secure-by-design principles alongside data-flow diagrams for threat modelling.
Key takeaways
- Validate input at the first trust boundary using explicit allowlists, schema checks, and sensible length and range limits.
- Treat validation, sanitisation, and encoding as different controls, and apply each one for the right purpose.
- Encode output according to the destination context, such as HTML, attributes, URLs, or JavaScript.
- Use server-side checks as the source of truth, because client-side validation can always be bypassed.
Why external input is a security boundary
Where untrusted data enters modern applications
Input does not only mean a text box on a website. Modern systems ingest JSON payloads, query parameters, headers, cookies, CSV files, image metadata, webhook events, message queue content, and synchronisation data from SaaS platforms. In cloud and microservice environments, even service-to-service traffic should be treated as untrusted until validated against a contract.
The key architectural point is that trust is not inherited from transport. TLS protects data in transit, but it does not make the content safe. Mutual authentication can confirm the peer, but it still does not guarantee that the payload is well formed or appropriate for the receiving component. A signed request can still contain malicious or malformed values if the sender is compromised or misconfigured.
How attackers abuse assumptions about input
Attackers look for places where the application assumes a value is harmless because it looks normal, comes from a logged-in user, or was previously processed by another layer. Common abuse patterns include SQL injection, command injection, cross-site scripting, server-side request forgery, path traversal, deserialisation issues, and logic abuse through unexpected values. Even when a direct exploit is not possible, malformed input can still trigger denial of service, parser confusion, or data quality failures.
From an architecture perspective, the risk is not limited to obvious injection flaws. Weak input handling can also undermine authorisation decisions, corrupt audit trails, break downstream integrations, and create inconsistent states that are hard to recover from. That is why input handling belongs in security architecture, not just in application coding standards.
What input validation actually does
Validation versus sanitisation versus encoding
These terms are often used interchangeably, but they do different jobs. Validation checks whether input meets the rules you expect. Sanitisation removes or alters unwanted content. Encoding transforms data so it is safe for a particular output context. They are complementary controls, not substitutes for one another.
Validation should answer questions such as: is this a number, is it within range, does it match the expected format, is the length acceptable, and is the value one of the permitted options. Sanitisation is useful when you need to clean user-facing content, but it should not be relied on as the primary security control. Encoding is what prevents data from being interpreted as code, markup, or control characters when it is rendered or passed into another parser.
A common mistake is to think that cleaning input once at the edge solves the problem everywhere. It does not. The same value may need to be validated at ingestion, normalised for storage, and encoded differently when displayed in HTML, inserted into a JavaScript string, or embedded in a URL. The right control depends on the context.
Why validation should happen as early as possible
Early validation reduces the blast radius of bad data. If you reject invalid input at the first trust boundary, you avoid propagating unsafe values through queues, caches, databases, and logs. That makes failures easier to diagnose and reduces the chance that a later component will interpret the value in an unsafe way.
There is also an operational benefit. Early rejection gives clearer error handling, simpler telemetry, and cleaner incident triage. If a request fails because it violates a schema or business rule, that should be visible immediately rather than surfacing later as a database error or a broken workflow.
Common validation approaches and when to use them
Allowlisting versus denylisting
Allowlisting means defining what is permitted and rejecting everything else. Denylisting means trying to block known bad patterns. For security-sensitive input, allowlisting is usually the stronger approach because it is easier to reason about and less likely to miss a new bypass technique.
Denylisting can still have a place, especially for defence in depth or for reducing nuisance content, but it should not be the primary control. If you are validating a country code, a product identifier, or a role name, it is usually better to specify the exact permitted values than to try to exclude every dangerous string.
For example, if a field should contain one of a small number of environment names, use a fixed set such as production, staging, and development. Do not accept arbitrary text and then attempt to strip suspicious words afterwards. The same principle applies to file extensions, MIME types, and enum-like fields in APIs.
Type, length, range, and format checks
Good validation is usually layered. Type checks confirm that the value is the expected kind of data. Length checks prevent oversized payloads and reduce resource abuse. Range checks make sure numbers are sensible. Format checks verify structure, such as email addresses, UUIDs, dates, or account references.
In practice, these checks should be explicit and close to the boundary. If a field is meant to be an integer between 1 and 100, reject anything outside that range before it reaches business logic. If a date must be in ISO 8601 format, parse it strictly rather than accepting multiple ambiguous formats. If a string should be a UUID, validate the canonical form and reject variants that your code does not need to support.
Length limits are especially important for resilience. They protect parsers, reduce memory pressure, and make log handling more predictable. A field that is technically valid but far larger than expected can still cause operational problems.
Practical examples of validation patterns
Validating form fields, API parameters, and file uploads
For form fields, use server-side validation even if the browser also performs checks. Client-side validation improves user experience, but it is not a security control because it can be bypassed. Server-side rules should be the source of truth and should mirror the business constraints of the field.
For API parameters, prefer schema-driven validation. In JSON APIs, define the expected shape, required fields, allowed types, and acceptable ranges. Tools such as OpenAPI validators, JSON Schema, or framework-native request validators can enforce this consistently. If a field is optional, make that explicit. If additional properties are not allowed, reject them rather than silently ignoring them.
File uploads need extra care. Validate the declared type, inspect the actual content, enforce size limits, and store the file outside executable paths. Do not rely on file extensions alone. If the file is meant to be an image, verify that it parses as the expected image format and strip metadata where appropriate. If the file is only needed for processing, consider quarantining it first and scanning it before release into the main workflow.
For teams using Python, a Pydantic model can enforce request structure at the API boundary. In TypeScript, Zod or Joi can provide similar schema validation. In Java, Bean Validation or framework-level request binding can be used to reject invalid payloads early. The exact tool matters less than the discipline of making validation declarative and centralised.
Handling unexpected character sets and encodings
Encoding problems are a common source of subtle bugs. A string that looks harmless in one encoding may become dangerous or invalid when interpreted in another. Normalise input to a known encoding, usually UTF-8, and reject malformed byte sequences rather than trying to guess the intent.
Be careful with Unicode normalisation, especially where identifiers, usernames, or security-sensitive tokens are involved. Different Unicode representations can look identical to a human but compare differently in code. If your application accepts international text, define where Unicode is allowed and where it is not. For security-critical identifiers, a narrower character set is often easier to support safely.
Also consider canonicalisation before validation. A path value, for example, should be normalised before you check whether it stays within an allowed directory. Otherwise, encoded separators or relative path segments may bypass naive checks. The same principle applies to URLs, file names, and any value that a downstream parser will reinterpret.
How validated inputs improve application security
Reducing injection risk and parser abuse
Validation reduces the number of values that reach dangerous sinks in a form that can be misinterpreted. If a database field only accepts a constrained set of characters or a strict numeric range, it becomes much harder for an attacker to smuggle control syntax into a query. If a command parameter is validated against a fixed set of options, the application is less likely to pass unexpected content to the shell.
This does not replace parameterised queries, safe APIs, or proper escaping. Those controls are still essential. But strong validation narrows the attack surface and reduces the chance that a coding mistake elsewhere becomes exploitable. It also helps protect parsers and libraries from malformed input that could trigger edge-case behaviour.
For web applications, this is especially relevant where user input is later used in templates, search filters, report generation, or workflow automation. If the data is constrained at the boundary, later components can make simpler assumptions and use safer code paths.
Improving reliability, logging, and downstream trust
Validated input is easier to log safely and analyse accurately. Logs become more useful when they contain values that conform to expected formats. Alerting rules are also easier to tune when the underlying data is consistent. In a SIEM, for example, structured and validated fields are far more useful than free-form strings that vary wildly between requests.
Downstream services benefit too. If one component can trust the schema of the data it receives, it can focus on business logic rather than defensive parsing. That improves maintainability and reduces duplicated validation logic across the stack.
This is one reason security architecture and operational design should be aligned. Input controls are not just about preventing attacks. They also improve observability, support cleaner incident response, and make change safer over time. If you are thinking about the wider architecture impact, secure system design for maintainability and observability is a useful companion topic.
Where encoding fits in the control stack
Output encoding for HTML, attributes, URLs, and JavaScript
Encoding is a rendering control. It makes sure that data is interpreted as data, not as executable content. The important point is that encoding is context-specific. HTML body text, HTML attributes, URLs, and JavaScript strings each require different handling.
For HTML output, encode special characters such as angle brackets and ampersands. For HTML attributes, ensure quotes and other delimiters are handled correctly. For URLs, percent-encode reserved characters as needed. For JavaScript contexts, avoid embedding untrusted data directly in script blocks where possible. If you must, use a safe serialisation method rather than hand-built string concatenation.
Do not assume that one generic escape function is enough for every context. A function that is safe for HTML may be unsafe for JavaScript or CSS. The safest pattern is to keep untrusted data out of executable contexts altogether and use framework features that handle context-aware encoding for you.
Why encoding is context-specific
The same value can be harmless in one context and dangerous in another. A string that is safe to display in a paragraph may break out of an attribute if inserted incorrectly. A value that is safe in a URL path may not be safe in a query string. A value that is safe in a database field may be unsafe when used in a shell command or template.
This is why output encoding should be applied as late as possible, at the point of use, and tailored to the sink. It is not a substitute for validation. Validation limits what enters the system; encoding limits how that data is interpreted when it leaves a component.
Defensive design patterns for technical teams
Schema validation at API boundaries
One of the most effective patterns is to validate all external requests against a schema at the edge of the service. That can happen in an API gateway, a middleware layer, or the service itself. The goal is to reject malformed requests before they reach business logic.
For REST APIs, this usually means defining request bodies, query parameters, and response shapes explicitly. For event-driven systems, it means validating message contracts before processing. For internal services, it means not assuming that data from another team or microservice is trustworthy just because it is inside the network.
Schema validation also supports versioning. If you need to add fields, you can do so deliberately and test the impact. If you need to deprecate fields, you can reject them in a controlled way. That is much safer than allowing arbitrary input and hoping the application copes.
Centralised validation libraries and shared rules
Validation rules should be reusable. If every team implements its own version of email, date, or identifier validation, you will get drift and inconsistent behaviour. Shared libraries or common middleware reduce that risk and make security review easier.
That said, centralisation should not become a bottleneck. Keep the library small, well tested, and versioned. Use it for common primitives and boundary checks, but allow product teams to define business-specific rules where needed. The aim is consistency, not rigidity.
Where possible, make validation declarative. A schema or policy file is easier to review than a long block of ad hoc string manipulation. It is also easier to test with negative cases, which matters when you are trying to prove that invalid input is rejected rather than merely handled somehow.
Testing and assurance for input handling
Abuse case testing and negative test coverage
Input handling should be tested with the same care as positive business flows. Negative tests are essential. Try empty values, oversized payloads, unexpected types, malformed encodings, boundary values, and values that are valid syntactically but invalid for the business rule.
Abuse case testing is especially useful for security-sensitive endpoints. Ask what happens if a field contains script-like content, path traversal sequences, SQL metacharacters, or nested objects where a scalar is expected. The point is not to build exploit payloads into your test suite, but to verify that the application rejects or safely handles malformed input.
Automated tests should cover both schema validation and output encoding. Unit tests can check that validators reject bad input. Integration tests can verify that the rendered output is encoded correctly in the target context. Security regression tests should be added whenever a new parser, template, or integration is introduced.
Using OWASP guidance and secure code review checks
OWASP guidance is useful here because it reinforces the practical distinction between validation, encoding, and safe sink usage. In code review, look for direct concatenation into SQL, shell commands, HTML, template engines, and file paths. Also check whether validation happens only in the browser or only in one service layer.
A good review question is: if this input were malicious, where would it first become dangerous? That helps identify the sink and the correct control. Another useful question is: what assumptions does the next component make about this value? If the answer is unclear, the architecture probably needs a stronger boundary.
If your team is building a broader secure development approach, it may also be worth aligning these checks with secure design reviews and architecture checkpoints so that input handling is reviewed before implementation becomes entrenched.
Common mistakes to avoid
Trusting client-side checks alone
Client-side validation is useful for usability, but it is not trustworthy. Browsers can be bypassed, requests can be replayed, and APIs can be called directly. Any rule that matters to security or data integrity must be enforced server-side.
That includes hidden fields, disabled controls, and values populated by JavaScript. If the server accepts a value, it must validate it as though it came from an untrusted source, because it did.
Over-relying on blacklists or ad hoc string cleaning
Blacklists are brittle. They tend to miss variants, encodings, and parser differences. Ad hoc string cleaning is also risky because it can create a false sense of safety while leaving the underlying trust problem unresolved.
Instead, define what good input looks like, reject everything else, and encode output according to context. Where data must be transformed, do so explicitly and consistently. If a value cannot be safely represented in the target context, do not force it through.
A practical implementation checklist
Start with the trust boundary. Identify every place where external data enters your application, service, or workflow. Then define the expected schema, permitted values, and length limits for each field. Reject anything that does not match.
Normalise and canonicalise before validating where the downstream interpretation depends on it, such as paths, URLs, and identifiers. Use server-side validation for every security-relevant rule. Keep client-side checks only as a convenience layer.
Apply output encoding at the point of use, and choose the encoding that matches the sink. HTML, attributes, URLs, and JavaScript all need different treatment. Avoid building executable strings with untrusted data where a safer API exists.
Test with negative cases, not just happy paths. Include malformed encodings, boundary values, and unexpected types in your automated tests. Review code for direct concatenation into dangerous sinks and for places where one component assumes another has already done the validation.
Finally, treat input handling as part of architecture, not just implementation. If you want to strengthen the design of your application boundaries, reduce injection risk, and make your controls easier to operate, a structured review can help. If that would be useful, speak to a consultant about practical support for your environment.
Frequently asked questions
What are three methods of validating user input?
Three common methods are allowlisting permitted values, checking type and range, and validating format with a schema or regular expression where appropriate.
How do properly validated inputs improve the security of an application?
They reduce the chance that malformed or malicious data reaches dangerous sinks, which lowers injection risk, improves parser reliability, and makes downstream components easier to trust.
Comments are closed