
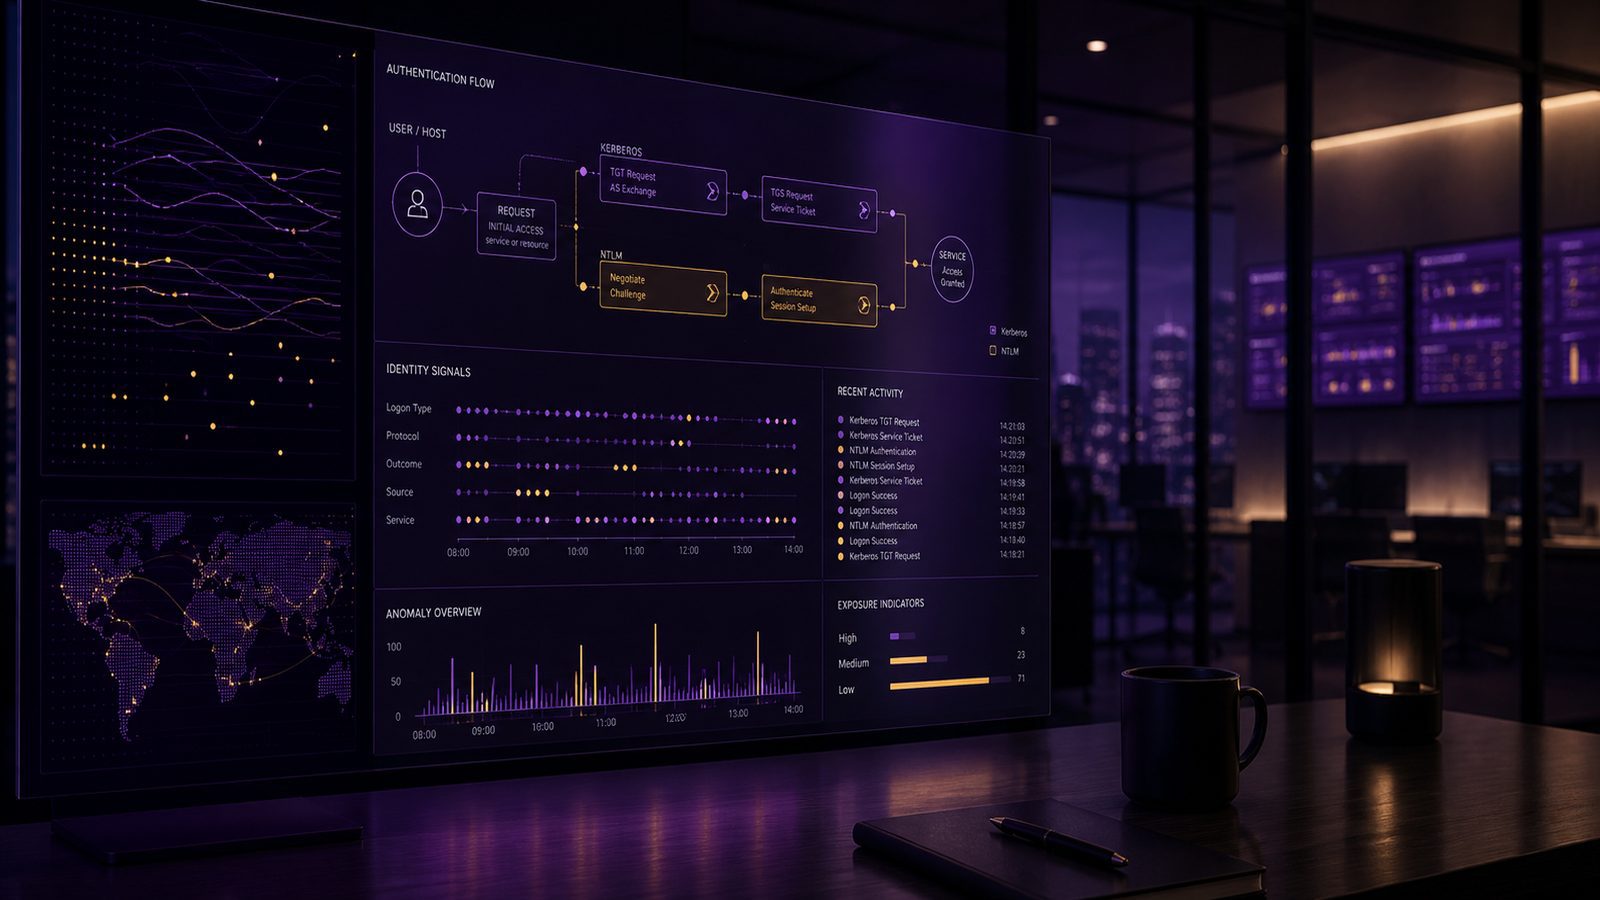
Kerberos and NTLM are still central to identity security in many enterprise environments, especially where Active Directory remains the core authentication layer and older applications still need legacy support. That makes them valuable to defenders, but also attractive to attackers who want to move laterally, replay credentials, or abuse trust relationships once they have a foothold.
For UK SMEs, the practical question is not whether these protocols are perfect. It is whether you can see how they are being used, spot abnormal patterns early, and investigate them with enough context to decide whether the activity is expected or suspicious. This article focuses on defensive detection, not exploitation, and assumes you want to improve visibility without turning your SOC or IT team into a full-time protocol research group.
Key takeaways
- Kerberos and NTLM detections work best when you correlate ticket, logon, endpoint, and asset context rather than relying on one event type.
- Event IDs 4768, 4769, 4776, 4624, and 4625 are a practical starting point for identifying unusual authentication behaviour in Windows estates.
- Baselines, allowlists, and time windows are essential for separating normal service activity from suspicious Kerberos or NTLM use.
- Reducing NTLM dependency and tightening service account hygiene will improve both security posture and detection quality.
- Map your detections to MITRE ATT&CK so you can measure coverage and spot gaps in identity monitoring.
Why Kerberos and NTLM abuse still matters in modern estates
In a fully modern cloud estate, you would expect identity traffic to be tightly controlled and mostly token-based. In reality, many organisations run hybrid Active Directory, domain-joined endpoints, line-of-business applications, file servers, print services, VPNs, remote access gateways, and third-party tools that still rely on Kerberos or NTLM. Even where Microsoft 365 or Entra ID is the primary front door, the on-premises estate often remains a high-value target because it still contains service accounts, delegated permissions, and privileged administration paths.
Abuse of authentication flows matters because it often sits in the middle of a broader intrusion chain. An attacker who can request unusual service tickets, force NTLM fallback, or replay captured credentials may not need to deploy obvious malware. Instead, they can blend into normal authentication noise while probing for privilege escalation opportunities. That is why identity telemetry should be treated as a first-class detection source alongside endpoint and network data. If you are building that broader visibility, it is worth aligning this work with your wider logging strategy, as described in our article on centralised visibility across endpoints, identity, and network.
What Kerberos and NTLM are, from a defender’s point of view
Kerberos is the preferred authentication protocol in modern Active Directory domains because it uses ticket-based authentication and reduces the need to send reusable credentials across the network. In normal use, a client requests a ticket-granting ticket, then uses that to request service tickets for specific resources. From a defender’s perspective, the important point is that Kerberos generates structured events on domain controllers and can be analysed for ticket request patterns, encryption types, and service principal names.
NTLM is older and less elegant. It is a challenge-response protocol that exists largely for compatibility with legacy systems, older applications, and certain cross-domain or misconfigured scenarios. It is still common enough that many environments cannot disable it immediately. The downside is that NTLM is easier to abuse in relay and replay scenarios, and it often appears when Kerberos cannot be used, which means it can be a signal of misconfiguration as well as malicious activity.
For defenders, the key difference is that Kerberos usually gives you richer ticket-level telemetry, while NTLM often requires you to infer risk from logon patterns, source systems, and authentication failures. That means your detections need to be tuned differently for each protocol.
Common abuse patterns to watch for
Kerberos abuse is often associated with ticket-based attacks such as Kerberoasting, AS-REP roasting, and ticket forgery or misuse. You do not need to model the offensive steps in detail to detect them. What matters is that these techniques tend to leave traces such as unusual service ticket requests, weak encryption types, requests for many service accounts in a short period, or authentication activity that does not fit the normal behaviour of a user or host.
NTLM abuse commonly shows up as relay attempts, pass-the-hash style credential replay, or suspicious fallback from Kerberos to NTLM when Kerberos should have been available. A sudden increase in NTLM traffic from a workstation that normally uses Kerberos, or NTLM authentication against systems that should not need it, is worth investigating. Repeated failures followed by success can also indicate credential guessing, relay attempts, or a misconfigured service account.
These patterns are often easier to interpret when you already understand the broader identity attack surface. If you want a wider view of how identity compromise develops, our article on detecting credential theft and misuse patterns is a useful companion piece.
How to tell whether Kerberos or NTLM is being used
The most useful starting point is Windows authentication telemetry from domain controllers, member servers, and endpoints. On domain controllers, Kerberos activity is commonly visible through Event ID 4768 for ticket-granting ticket requests and Event ID 4769 for service ticket requests. NTLM activity is often visible through Event ID 4776, which records NTLM authentication validation attempts. On endpoints and servers, logon events such as 4624 and 4625 can help you understand the authentication type, logon process, and source host.
In practice, you want to correlate these events rather than treat them in isolation. For example, a 4624 logon with a network logon type on a server, followed by a 4769 request for an unusual service principal name, may be normal if it matches a scheduled task or service account. The same sequence from a workstation at an odd time, or from a host that rarely talks to that service, deserves more scrutiny. If you are already collecting Sysmon and Windows event logs, that telemetry can help you tie authentication to process creation and network connections, which improves confidence in your detections. Our guide to detecting malicious activity using Sysmon and Windows Event Logs covers the telemetry side in more depth.
Identity platforms can also help. In hybrid estates, Entra ID sign-in logs, conditional access outcomes, and device compliance context can show whether authentication is happening from a managed endpoint, a browser session, or a legacy protocol path. That context is especially useful when you are trying to distinguish a genuine application dependency from a suspicious fallback.
Detection logic for Kerberos abuse
Event ID 4769 is one of the most useful sources for Kerberos detection engineering. A single ticket request is not interesting on its own, but patterns are. Look for service ticket requests with encryption types that are weaker than expected for your environment, especially where RC4 appears in places you would normally expect AES. Also look for a high volume of requests for distinct service accounts from one source host, or repeated requests for the same service principal name across many accounts in a short window.
Another useful signal is the relationship between the user, the source host, and the service being requested. A user requesting tickets for a service they never normally access, from a device they do not usually use, is more interesting than a request from a known application server. This is where baselining matters. Build a view of normal service ticket behaviour by host class, user group, and time of day, then alert on deviations rather than raw event counts.
In Microsoft Sentinel, a simple starting point might be a KQL query that groups 4769 events by Account, ServiceName, and ClientAddress, then flags unusual spikes or first-seen combinations. In Splunk, you can do the same with a `stats` aggregation over `EventCode=4769`, then enrich with asset and identity context. In Defender for Endpoint, you can use device and identity correlation to see whether the ticket request aligns with suspicious process activity on the source host.
If you are specifically interested in ticket abuse patterns, our article on detecting Golden Ticket and Silver Ticket attacks in Kerberos logs goes deeper into the Kerberos log side without repeating the broader identity context here.
Detection logic for NTLM abuse
NTLM detections are usually more about context than a single event type. Event ID 4776 is useful because it records NTLM validation attempts on domain controllers, but you need to understand whether the source, destination, and frequency fit normal behaviour. A workstation that suddenly starts authenticating to multiple servers using NTLM, especially if those servers normally accept Kerberos, is a candidate for investigation.
Look for repeated authentication failures followed by success, especially where the source host is unusual or the account involved is privileged. Also watch for NTLM use from systems that should be using Kerberos exclusively, such as modern domain-joined Windows endpoints talking to internal services. If you see NTLM being used for administrative access, remote management, or service-to-service communication, that may indicate legacy configuration, but it can also indicate an opportunity for relay or replay.
Logon type matters as well. Network logons, remote interactive logons, and service logons each have different risk profiles. A service account authenticating with NTLM during a scheduled maintenance window may be expected. The same account authenticating from a user workstation outside that window is not. Enriching authentication events with asset role, owner, and usual schedule is one of the simplest ways to reduce noise.
Building higher-fidelity detections
High-fidelity detections usually come from combining weak signals rather than relying on one event. For Kerberos, that might mean pairing 4769 ticket requests with unusual encryption types, first-seen service principal names, and a source host that has no obvious business reason to access the service. For NTLM, it might mean pairing 4776 validation events with repeated failures, unusual source systems, and a logon type that does not match the account’s normal use.
Allowlisting is useful, but it should be controlled. Do not build a giant static list of exceptions and forget about it. Instead, maintain a small set of known service accounts, management hosts, and application servers that are reviewed regularly. Time windows also help. Scheduled jobs, patching activity, and backup operations often create authentication bursts that look suspicious if you do not account for them.
Asset context is often the difference between a noisy alert and a useful one. If your SIEM can enrich events with host role, business owner, and criticality, you can treat a Kerberos request from a domain controller differently from the same request from a finance laptop. That is a practical application of risk-based detection engineering, and it is especially important for smaller teams that cannot investigate every alert manually.
Investigation workflow for SOC and IT teams
When a Kerberos or NTLM alert fires, start by confirming whether the activity matches a known service, scheduled task, or administrative action. Check the account, source host, destination service, and time of day. Then look for adjacent events on the same host and account. A suspicious ticket request becomes more meaningful if you also see a new process launch, unusual remote access, or a failed logon sequence.
Next, correlate identity and endpoint evidence. On the endpoint, look for process creation, script execution, remote service creation, or suspicious parent-child process chains. On the identity side, look for privilege changes, group membership changes, or unusual logon patterns. On the network side, look for connections to internal services that the source host does not normally use. This is where a broader detection stack pays off, because authentication abuse rarely exists in isolation.
If you need a reminder of how identity compromise often unfolds across the estate, our article on detecting fileless malware and living-off-the-land attacks is relevant because many identity abuse cases rely on legitimate tools rather than obvious malware.
Hardening measures that reduce exposure
Detection is important, but you will get better outcomes if you reduce the amount of risky authentication in the first place. Where possible, reduce NTLM usage by identifying legacy dependencies and replacing them with Kerberos-capable or modern authentication flows. In Windows environments, review NTLM audit data before making changes, because some applications still depend on it in ways that are not obvious until you test.
For Kerberos, focus on service account hygiene. Use strong, unique passwords or managed service accounts where appropriate, review service principal names, and remove stale or duplicate service registrations. Make sure privileged accounts are not used for routine service access. Enforce tiering where possible so that administrative identities are not used on lower-trust systems.
Logging also matters. Make sure domain controllers, key servers, and critical endpoints are forwarding the right event IDs into your SIEM. If you cannot see 4768, 4769, 4776, 4624, and 4625 consistently, your detection coverage will be patchy. That is often a more immediate issue than the detection logic itself.
How to operationalise this in Microsoft Sentinel, Splunk, or Defender
In Microsoft Sentinel, build analytics rules around 4769 and 4776 with enrichment from device inventory and identity risk context. Use KQL to aggregate by account, source host, and service, then apply thresholds that reflect your environment rather than generic values. Sentinel is particularly useful if you already ingest Entra ID and Defender telemetry, because you can correlate identity, endpoint, and cloud signals in one place.
In Splunk, normalise Windows security events into a consistent data model, then create correlation searches that look for first-seen service names, unusual encryption types, and repeated NTLM validation failures. Splunk’s strength is flexible search and enrichment, but only if your field mapping is consistent. Without that, Kerberos and NTLM detections become hard to maintain.
In Microsoft Defender for Endpoint, use advanced hunting to connect authentication events with device behaviour. For example, a suspicious ticket request becomes more actionable if the same device also shows credential dumping indicators, unusual PowerShell activity, or remote execution. That is where identity detections and endpoint detections reinforce each other rather than compete for attention.
Whatever platform you use, map the detections to MITRE ATT&CK so you can track coverage and gaps. Kerberos abuse and NTLM abuse often sit under credential access and lateral movement techniques, but the exact mapping depends on the behaviour you are detecting. A simple coverage matrix helps you see whether you are only detecting one narrow pattern or whether you have visibility across the wider attack path.
Practical priorities for smaller security teams
If you are a small team, do not try to solve everything at once. Start with the minimum viable telemetry: domain controller security logs, endpoint logon events, and a small set of critical server logs. Then build a short list of high-value detections, such as unusual 4769 patterns, unexpected NTLM use, and repeated authentication failures from unusual hosts.
After that, tune the detections using real incidents, benign exceptions, and scheduled activity. Keep a simple runbook for each alert type so analysts know what to check first and what evidence to preserve. Review false positives regularly, because identity detections tend to drift as applications change, service accounts are added, and infrastructure evolves.
Finally, treat this as an iterative programme rather than a one-off project. The goal is not perfect detection on day one. The goal is to steadily improve your ability to see abnormal authentication behaviour, investigate it quickly, and reduce the number of places where legacy authentication creates unnecessary risk.
If you want help turning this into a practical detection roadmap, or you need support aligning identity logging, SIEM content, and control improvements, Speak to a consultant.
Frequently asked questions
How can you check if Kerberos or NTLM is being used?
On Windows estates, Kerberos activity is usually visible in domain controller events such as 4768 and 4769, while NTLM validation is commonly visible in 4776. You can confirm the protocol in use by correlating those events with logon events such as 4624 and 4625, then checking the source host, destination service, and authentication context.
Is NTLM better than Kerberos?
No. Kerberos is generally the preferred protocol because it is better suited to modern Active Directory environments and gives defenders richer ticket-based telemetry. NTLM still exists for compatibility, but it should be treated as a legacy dependency to reduce where possible rather than a better default.
Comments are closed