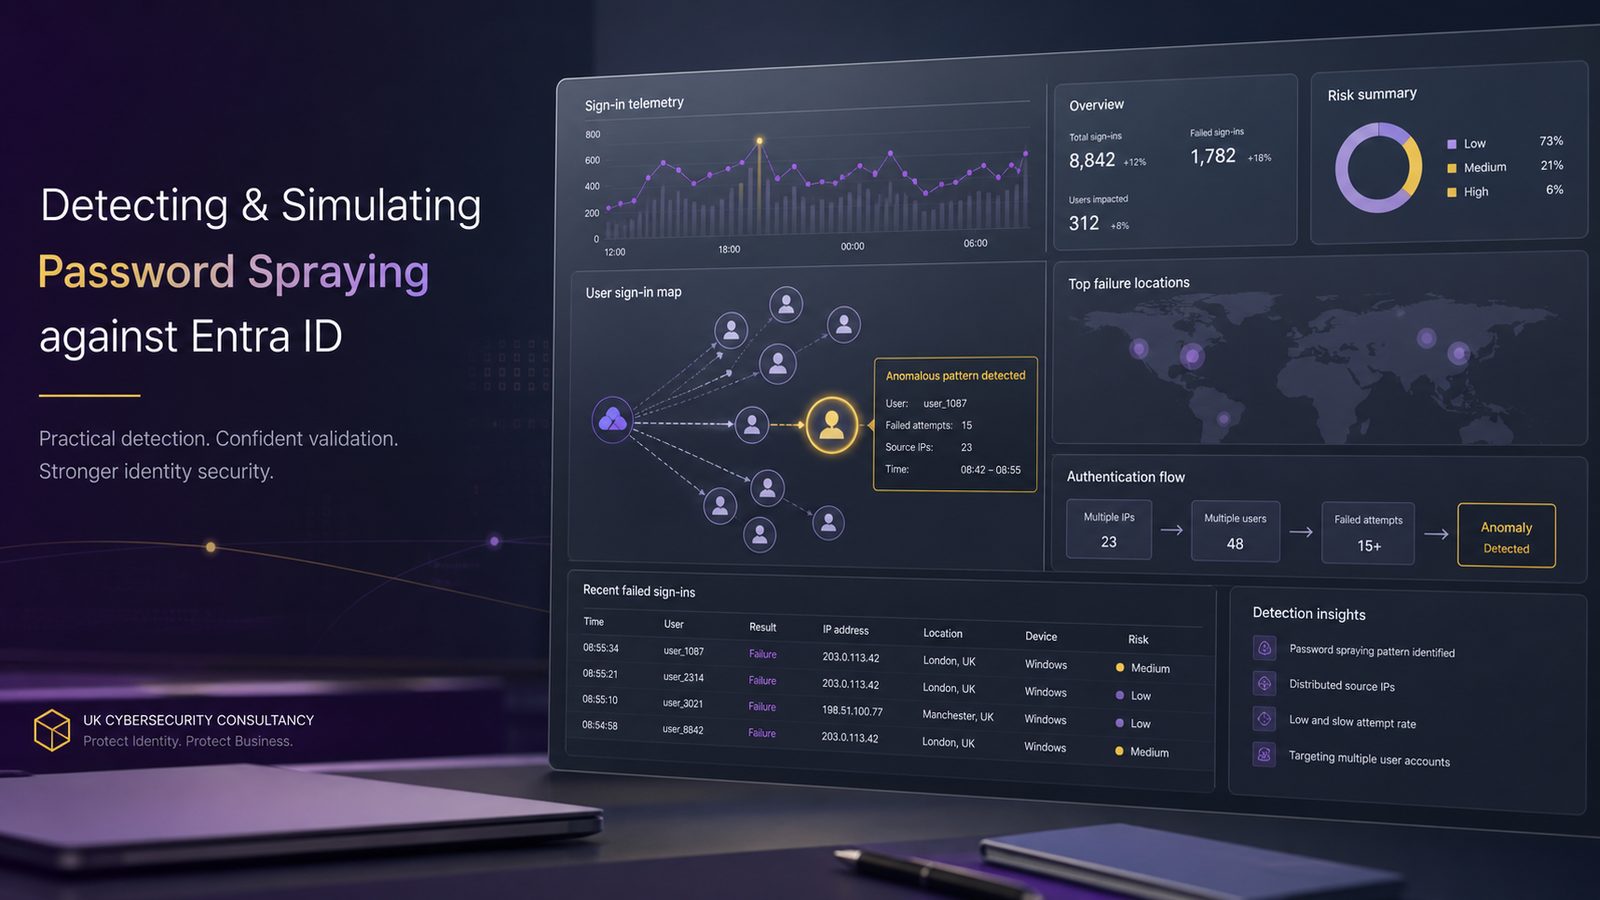
Password spraying against Entra ID remains one of the more practical identity attack patterns to defend against because it is designed to look ordinary. Rather than hammering a single account with repeated guesses, the attacker tries a small number of common passwords across many accounts. That low-and-slow approach is intended to stay below lockout thresholds and avoid obvious brute-force signals.
For UK SMEs, the issue is not only account compromise. A successful spray can lead to mailbox access, token theft, business email compromise, and lateral movement into Microsoft 365 workloads. If your organisation relies on Entra ID for single sign-on, the identity layer is effectively the front door to a large part of the environment. That makes detection engineering and safe validation worth doing properly, not as a one-off exercise.
Key takeaways
- Password spraying against Entra ID is best detected by correlating failed sign-ins across many users, source IPs, and short time windows.
- MFA, conditional access, and legacy authentication controls reduce spray success, but they need to be validated against the actual sign-in paths in use.
- Safe validation should use approved test accounts, controlled conditions, and repeatable emulation rather than ad hoc live testing.
- A useful investigation checks source IPs, successful follow-on sign-ins, and post-authentication activity such as mailbox access or token abuse.
What password spraying looks like in Entra ID
In Entra ID, password spraying usually appears as a small set of failed sign-in attempts spread across many users, often from the same source IP address or a small cluster of addresses. The attacker may target cloud-only accounts, hybrid identities, or any account that looks likely to have weak password hygiene. The pattern is often intermittent, with pauses between attempts to reduce the chance of triggering rate-based controls.
How it differs from brute force and credential stuffing
Brute force is noisy. It focuses on one account and cycles through many passwords until it succeeds or the account locks. Credential stuffing is different again, because it uses previously leaked username and password pairs from other breaches. Password spraying sits between the two. It uses a small number of common passwords, but applies them across many accounts to avoid lockouts and reduce alert volume.
That distinction matters when you build detections. If your logic only looks for repeated failures on a single account, you will miss the distributed nature of spraying. If you only alert on impossible travel or successful sign-ins, you may detect compromise too late. A better approach is to correlate users, source IPs, time windows, and authentication outcomes.
Why attackers target Microsoft 365 and Entra ID tenants
Microsoft 365 tenants are attractive because a single successful login can expose email, files, collaboration data, and downstream SaaS access. Entra ID also sits at the centre of many conditional access policies, so a compromised identity can become a pivot point for further abuse. In practice, attackers often prefer identity compromise over endpoint compromise because it can be quieter and faster to monetise.
If you are already thinking about identity hardening, it is worth pairing this work with broader Zero Trust architectures with Entra ID so that detection and prevention are designed together rather than as separate projects.
What security measure password spraying is trying to bypass
Password spraying is not trying to defeat strong cryptography. It is trying to exploit the way organisations balance usability and protection. The attacker assumes that some users still have weak passwords, that lockout thresholds are tuned to avoid helpdesk noise, and that legacy authentication paths may still exist somewhere in the tenant.
How low-and-slow attempts evade lockout thresholds
Traditional account lockout controls are less effective when the attacker only makes one or two attempts per account. If the threshold is set to five failures, a spray that makes one failure per user across hundreds of users may never trip it. That is why modern identity protection needs to focus on behavioural patterns, not just per-account counters.
From a detection perspective, this means you should track failed sign-ins by source, by user population, and by time bucket. A source that generates a modest number of failures across many accounts in a short period is more suspicious than a single account with a handful of failures over a week.
Why MFA, conditional access, and legacy authentication settings matter
Multi-factor authentication reduces the value of a guessed password, but it is not a complete answer if the tenant still allows legacy protocols or weak conditional access coverage. Legacy authentication, such as older mail protocols, may not support modern controls in the same way as interactive browser sign-ins. If those paths remain enabled, they can become the easier route for an attacker.
Conditional access is also important because it lets you require stronger controls for risky sign-ins, unfamiliar locations, or unmanaged devices. The practical point is that detection and prevention should reinforce each other. If your detections show spray activity but your policies still allow the same attack path, you are only observing the problem, not reducing it.
Telemetry to collect before you build detections
Good detections depend on good telemetry. Before you write KQL, confirm that the logs you need are actually available, retained long enough, and normalised into your SIEM in a usable way. For Entra ID spraying, the minimum useful dataset is sign-in telemetry with enough context to distinguish interactive, non-interactive, and failed authentication attempts.
Entra ID sign-in logs and audit logs
Start with Entra ID sign-in logs. These provide the core fields you need for spray detection, including user principal name, IP address, application, result type, conditional access outcome, and authentication requirement. Audit logs are less central for the spray itself, but they help when you want to understand changes to identity configuration, such as policy edits, MFA registration changes, or account modifications around the same time.
Make sure you understand which log source you are using. In Microsoft Sentinel, Entra ID sign-in logs may arrive through the relevant connector and can be queried alongside other identity data. If you only ingest a subset of fields, your detection quality will suffer. For example, losing client app or authentication requirement data can make it harder to separate browser-based user activity from protocol abuse.
Microsoft Defender for Cloud Apps, Sentinel, and identity protection signals
Defender for Cloud Apps can add useful context where cloud app activity follows a suspicious sign-in. Microsoft Sentinel gives you the correlation layer and the alerting workflow. Entra ID Identity Protection signals are also valuable because they can surface risky users, risky sign-ins, and related risk events that strengthen triage.
In a small team, the goal is not to collect every possible signal. It is to collect the signals that let you answer three questions quickly: was there a spray pattern, did any account succeed, and did the successful account do anything suspicious afterwards?
Detection logic for password spraying
High-quality spray detection usually combines several weak signals rather than relying on one perfect indicator. The most useful patterns are repeated failures across many users from the same source, a short time window, and a low failure count per user. You can also look for repeated attempts against accounts that share a naming pattern, department, or domain suffix.
High-fidelity patterns to look for across users, IPs, and time windows
A practical rule is to alert when one IP address or one ASN generates failed sign-ins for a threshold number of distinct users within a defined window, such as 10 to 30 minutes. You can refine this by excluding known corporate egress points, VPN concentrators, and trusted testing ranges. Another useful pattern is a burst of failures followed by a single success from the same source or a closely related source set.
It also helps to separate interactive and non-interactive sign-ins. Password sprays may target both, but the context differs. A successful non-interactive sign-in can indicate token or protocol abuse, while a successful interactive sign-in may be the start of mailbox access or consent abuse.
Useful KQL approaches for Microsoft Sentinel and related SIEMs
In Microsoft Sentinel, a common starting point is a query over Entra ID sign-in logs that summarises failed attempts by IP address and distinct user count. The exact schema depends on your connector and workspace, but the pattern is straightforward: filter on failed result types, bin by time, summarise distinct users, and alert when the count crosses your threshold.
For example, you might build logic around fields such as IP address, user principal name, result type, app display name, and conditional access status. A simplified approach is to use a summarize over a 15-minute window, count distinct users per IP, and then join to any successful sign-in from the same source in the same period. That gives you a more actionable alert than a raw failure count.
If you are already building detections in KQL, it is worth aligning them with your broader detection engineering approach, as discussed in building SIEM detections using Sigma rules. The same principles apply here: define the behaviour, normalise the fields, and tune for operational usefulness rather than theoretical completeness.
How to tune for false positives and noisy environments
Identity detections are easy to over-tune or under-tune. If you make the threshold too low, every busy VPN or remote workforce pattern becomes an alert. If you make it too high, you miss the spray. The right answer depends on your user population, authentication architecture, and external exposure.
Separating legitimate user behaviour from attack traffic
Start by building an allow list for known corporate egress IPs, but do not stop there. Legitimate users can still generate failures from home networks, mobile connections, or travel locations. Look at the shape of the activity. Real user mistakes usually involve a small number of attempts against one account, often followed by a successful login from the same device or location. Spray activity is broader and flatter.
It is also useful to compare the source IP against historical behaviour. If an IP has never been seen before and suddenly touches many accounts, that is more interesting than a known office IP with a few failures. Geo-location can help, but it should not be your only signal because VPNs and cloud hosting can distort it.
Handling VPNs, shared egress, and remote work patterns
Shared egress is one of the main reasons spray detections become noisy. A large office, a remote access gateway, or a secure web proxy can make many users appear to come from the same IP. In those cases, add more context such as user agent, client app, device compliance, and authentication method. If the same source IP is associated with many different user agents and repeated failures across unrelated accounts, that is more suspicious than a single corporate gateway with normal traffic.
Where possible, segment your logic by authentication path. Browser sign-ins, legacy protocol attempts, and non-interactive token use often need different thresholds. A single detection rule rarely fits all of them well.
Safe ways to simulate password spraying for validation
Validation should be controlled, documented, and limited to accounts and tenants you are authorised to test. The aim is to prove that your detections, alerts, and response steps work, not to recreate a real attack at scale. Use approved test accounts, a lab tenant where possible, and a narrow test window with clear change control.
Using approved test accounts and controlled lab or tenant conditions
The safest approach is to create a small set of dedicated test accounts with known passwords and explicit approval from the tenant owner. Then generate a very small number of failed sign-in attempts across those accounts from a controlled source so that you can observe whether the SIEM rule fires, whether the alert contains the right context, and whether the response team can triage it quickly.
Keep the test environment separate from production where possible. If you must test in production, use a maintenance window, notify the service desk, and ensure the test source is clearly identifiable in logs. That reduces the risk of confusion if the activity is seen by analysts or end users.
Validating detections with Atomic Red Team or similar safe emulation tooling
Safe emulation tooling can help you validate the detection path without building custom attack scripts. Atomic Red Team is useful because it maps tests to ATT&CK techniques and supports repeatable validation. For identity-focused tests, the important point is not the tool itself but the discipline around it: use a controlled test case, confirm the expected telemetry, and document the outcome.
If you are already using purple-team style validation, this is a good place to extend that work. You can pair the identity test with alert routing, ticket creation, and escalation checks so that you are validating the whole workflow, not just the detection query. That is consistent with the broader approach in simulating adversary techniques safely with Atomic Red Team.
What to test in your control stack
Detection is only one layer. You should also verify that the controls intended to stop or slow a spray are actually enforced. That includes MFA coverage, conditional access policy scope, legacy authentication blocks, and the quality of your alerting and response process.
MFA enforcement, legacy authentication blocks, and risk-based sign-in policies
Check whether MFA is required for all users, not just privileged accounts. Then confirm that the policy applies to the sign-in paths you care about, including browser, mobile, and protocol-based access where possible. If legacy authentication is still allowed for any reason, document the exception and treat it as a risk that needs active monitoring.
Risk-based sign-in policies can help, but only if they are tuned and monitored. A risky sign-in that is not acted on quickly may still become a successful compromise. If you have a policy that blocks or challenges suspicious activity, test that the enforcement path works as expected and that the user experience does not create unnecessary support noise.
Alerting, escalation, and containment workflows
When a spray alert fires, the response should be simple. Confirm whether the source is known, whether any account succeeded, whether the successful account has recent mailbox or file activity, and whether the sign-in is associated with a risky location or client app. If the alert is credible, the next steps may include forcing password resets, revoking sessions, and reviewing conditional access logs for the affected accounts.
It is also worth checking that your SOC or IT team knows who owns identity containment. In small organisations, the delay is often not technical. It is uncertainty about who can disable an account, revoke refresh tokens, or change policy quickly enough.
Investigation workflow when a spray is suspected
When you suspect a spray, start with the source. Identify the IP addresses, user agents, and time range. Then identify the target population and whether the attempts were spread across many users or concentrated on a subset such as executives, finance users, or administrators. That helps you understand whether the activity was opportunistic or targeted.
Next, look for any successful sign-ins from the same source or nearby sources. If there was a success, inspect the post-authentication activity. Check mailbox access, file downloads, consent grants, new inbox rules, forwarding changes, and unusual token use. In Entra ID, a successful sign-in is often only the beginning of the incident.
Finally, compare the activity to your normal baseline. If the source IP belongs to a known VPN or remote access service, check whether the user population and timing match expected usage. If not, treat it as suspicious until proven otherwise.
Hardening steps that reduce spray success
The most effective hardening measures are usually the least glamorous. Disable legacy protocols where you can, require MFA broadly, and make sure conditional access is applied consistently. Review privileged accounts separately and reduce the number of accounts that can bypass normal controls.
Improve identity hygiene by removing stale accounts, enforcing stronger password policies where appropriate, and ensuring that account recovery processes are not weaker than the login controls themselves. If you have service accounts or shared accounts, document them carefully and monitor them more closely because they often sit outside normal user behaviour.
For many SMEs, the biggest improvement comes from better visibility and tighter policy scope rather than from adding more tools. If you want to strengthen the overall identity posture, it is sensible to connect spray detection with the broader control design discussed in designing Zero Trust architectures with Entra ID.
How to measure whether your detections are working
Detection quality should be measured, not assumed. Useful metrics include coverage, precision, time to alert, and time to triage. Coverage tells you whether the relevant log sources are present. Precision tells you whether the alerts are meaningful. Time to alert and time to triage show whether the workflow is operationally useful.
Track how many spray-like events your rule catches during validation, how many false positives it generates from VPN or remote work traffic, and how often the rule needs tuning after environment changes. If your tenant grows, your thresholds may need to change as well.
Use purple-team style validation on a regular cadence. That does not need to be elaborate. A short, controlled test every quarter can be enough to confirm that the logs still flow, the query still matches the right fields, and the response steps still work. The value is in keeping the detection current as the environment changes.
When to get outside help
Specialist support is often useful when your identity telemetry is incomplete, your tenant has multiple authentication paths, or your team does not have time to build and tune detections properly. It is also helpful if you need to align identity monitoring with a wider proactive testing programme, such as threat-led penetration testing or purple teaming.
If you are unsure whether your current controls would actually stop or detect a spray, a structured review can save time. That review can cover log coverage, detection logic, conditional access design, and response readiness. It can also help you decide whether the issue is best solved through policy changes, SIEM engineering, or a mix of both.
For organisations that want practical support with identity detection, Entra ID hardening, or broader proactive security testing, speak to a consultant.
Frequently asked questions
How do you detect password spraying in Entra ID?
Look for repeated failed sign-ins across many distinct users from the same source IP or small IP set within a short time window, then correlate that pattern with any successful sign-in and follow-on activity. In Microsoft Sentinel, KQL summarisation over Entra ID sign-in logs is usually the most practical starting point.
How can you simulate password spraying safely without creating risk?
Use approved test accounts, a controlled source, and a narrow test window, ideally in a lab or isolated tenant. The goal is to validate logging, alerting, and response workflows with minimal failed attempts, not to reproduce a real attack at scale.
Comments are closed