Security teams often reach a point where alerts are arriving faster than people can triage them. At that stage, the question is not whether to automate, but what to automate, how far to automate, and how to keep control when the workflow touches production systems. That is where automated response and SOAR design patterns become useful.
SOAR, or security orchestration, automation and response, is best treated as a control layer that coordinates actions across tools and teams. It is not a replacement for detection engineering, and it is not a shortcut around analyst judgement. For UK SMEs, the practical goal is usually to reduce time to contain common events, standardise response, and remove repetitive manual work without creating a brittle or risky automation estate.
If you are already centralising telemetry in a SIEM or XDR platform, SOAR can sit on top of that stack and turn detections into structured workflows. If you are still maturing your logging and alerting, it is worth reading centralised security visibility and achieving centralised visibility across endpoints, identity, and network first, because automation is only as good as the signals it consumes.
Key takeaways
- Start with enrichment and case management before automating containment actions.
- Use confidence thresholds, approval gates, and rollback paths for any response that can affect users or services.
- Treat SOAR as orchestration around SIEM, XDR, EDR, and IAM, not as a replacement for detection engineering.
- Measure containment time, analyst effort, false positives, and playbook drift to prove value over time.
What SOAR automation is and where it fits in the security stack
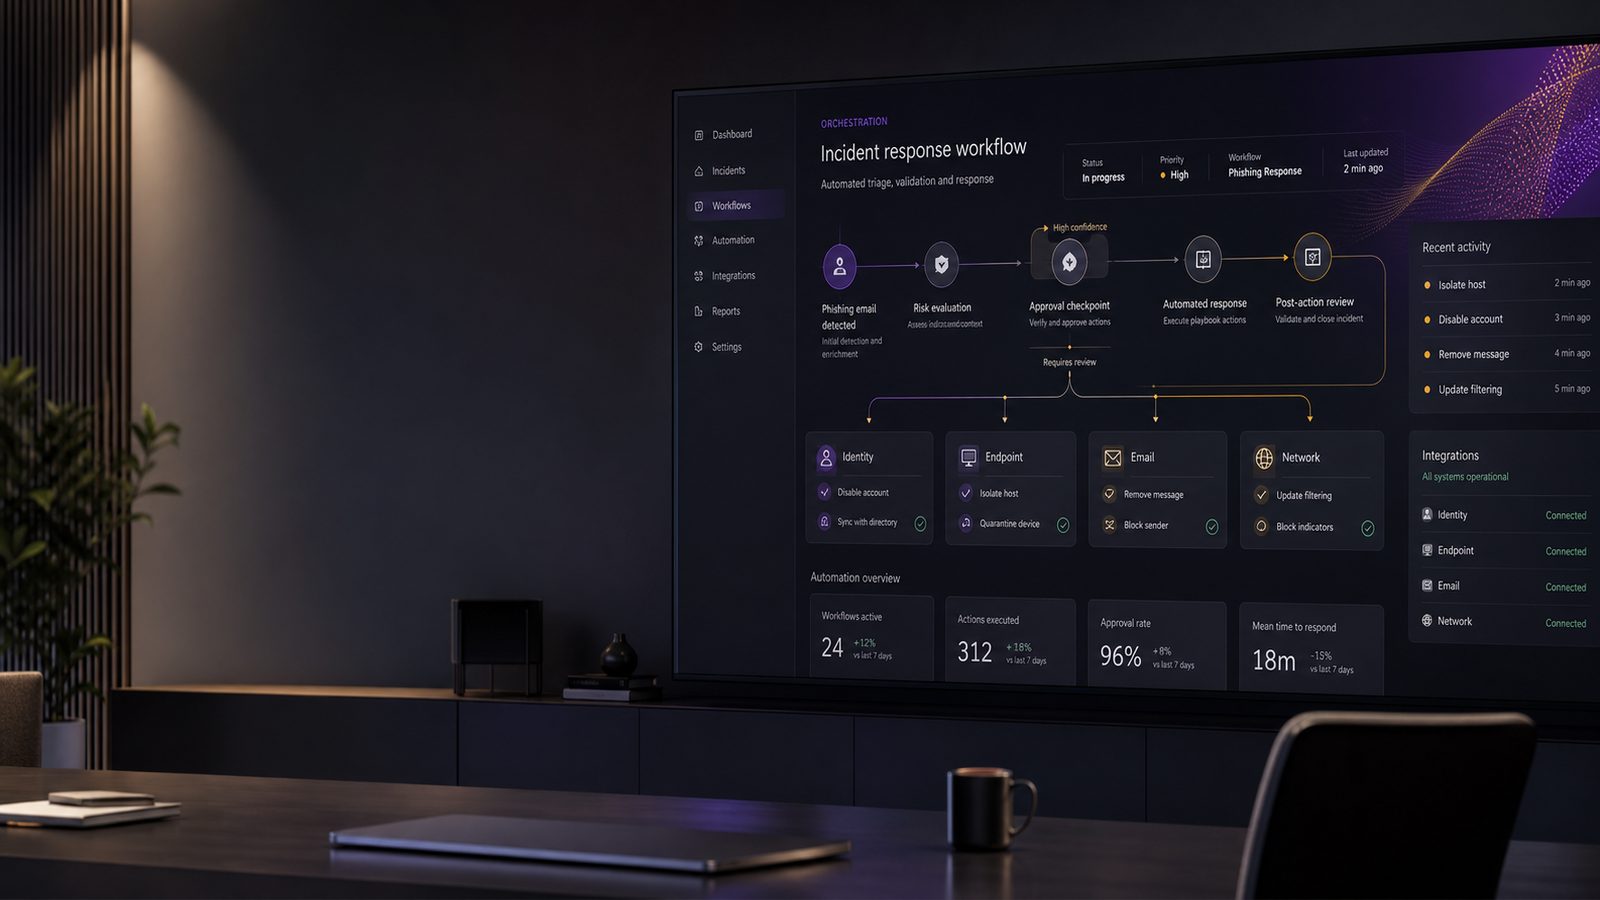
SOAR platforms typically ingest alerts from a SIEM, XDR, email security gateway, endpoint protection platform, identity provider, ticketing system, or cloud control plane. They then orchestrate a sequence of actions such as enrichment, correlation, case creation, notification, containment, and closure. In practice, the value comes from turning a noisy event into a repeatable response path.
The distinction between the main layers matters. A SIEM aggregates and correlates logs. XDR extends detection across endpoint, identity, email, and sometimes network telemetry. EDR focuses on endpoint detection and response. SOAR does not usually replace any of these. Instead, it consumes their output and coordinates the next steps. In a mature environment, a SIEM may raise a high-confidence alert, XDR may provide context, and SOAR may open a case, enrich it with asset and identity data, isolate a device, and assign the incident to an analyst.
That orchestration role is why SOAR is often most effective in environments with a limited security team. A small team does not need to automate everything. It needs to automate the parts that are repetitive, well understood, and low risk when executed correctly. That usually includes enrichment, ticket routing, evidence collection, and some containment actions with clear guardrails.
What good automation should not do is equally important. It should not hide uncertainty, make irreversible changes without controls, or attempt to “solve” ambiguous detections by force. If the detection quality is poor, automation will simply accelerate bad decisions. If the response action is high impact, such as disabling a privileged account or blocking a business-critical service, the workflow needs explicit approval and a fallback path.
Core design principles for safe automated response
The first design principle is to separate decision support from action execution. A playbook can gather context, score the event, and recommend a response, but the final action should depend on the confidence level and the business impact of the control being triggered. This is especially important where the same automation could affect a user, a server, or a customer-facing service.
Human approval gates are most useful for actions that are difficult to reverse or likely to interrupt business operations. Examples include disabling accounts, revoking tokens, quarantining mailboxes, blocking IP ranges at the edge, or isolating endpoints used by senior staff or shared service accounts. Lower-risk actions, such as adding tags, creating tickets, enriching alerts, or notifying a channel, can usually be fully automated.
Idempotency is another design requirement that is often overlooked. A playbook should be safe to run more than once without causing duplicate or conflicting actions. For example, if a workflow isolates an endpoint, the second execution should confirm the endpoint is already isolated rather than attempting a second isolation request. This matters because retries, duplicate alerts, and API timeouts are normal in production systems.
Rollback and blast-radius control should be designed in from the start. If a workflow blocks a user, there should be a documented way to restore access quickly after validation. If a firewall rule is added, there should be a time-bound expiry or a clear removal step. If a cloud resource is tagged or moved into a restricted state, the playbook should record the original state so it can be restored cleanly.
Blast-radius control also means limiting scope. Do not write a single generic “containment” playbook that can touch every asset in the estate. Instead, create separate workflows for endpoints, identities, email, and network controls. That keeps permissions narrow, testing simpler, and failure modes easier to understand. It also aligns well with least privilege and with the broader principle of reducing attack surface across applications and infrastructure.
Common SOAR design patterns used in practice
The most useful SOAR pattern for many SMEs is alert enrichment and triage. The workflow starts when a detection fires, then pulls in asset criticality, user role, recent authentication history, endpoint posture, geolocation, threat intelligence, and previous incidents. The output is a more complete case for the analyst, not an immediate containment action. This pattern is ideal for early maturity because it improves decision quality without taking on much operational risk.
A practical enrichment workflow might query the SIEM for related events, call the identity provider for sign-in context, check the endpoint platform for device health, and look up the host in a CMDB or asset inventory. The case can then be scored using a simple rules-based model. For example, a failed login alert against a privileged account on a managed device during business hours may be routed differently from the same alert against an unmanaged device from an unusual country.
The next pattern is containment and remediation. This is where SOAR starts to take direct action, but it should still be tightly bounded. Common examples include isolating an endpoint, disabling a suspicious mailbox rule, forcing a password reset, revoking active sessions, or blocking a malicious sender. These actions are suitable when the detection is high confidence, the response is reversible, and the business impact is understood.
For identity-driven response, integration with Entra ID or another IAM platform is often the most effective place to start. If a detection indicates account compromise, the playbook can revoke refresh tokens, require re-authentication, reset the password, and step up the user’s risk state. If the account is privileged, the workflow may also remove active role assignments temporarily. The key is to use the identity layer as a control point rather than trying to solve identity risk only at the endpoint or network layer.
The third pattern is case management and handoff. Not every alert should end in automation. Some should be converted into a structured case with the right context, assigned to the right queue, and tracked through to closure. A good SOAR workflow can create the case, attach evidence, set severity, notify the on-call analyst, and preserve the timeline. This is particularly useful where the organisation needs a consistent audit trail for incident handling and internal review.
Where this becomes especially valuable is in organisations that already have a mature detection pipeline but inconsistent response habits. In those environments, SOAR is less about “doing more” and more about making response repeatable. That is also why it pairs well with secure system design for maintainability and observability, because the same discipline that helps you operate systems safely also helps you automate response safely.
Building playbooks around detection quality
Automation should follow detection quality, not lead it. If an alert has a high false positive rate, automating response around it will create noise, user disruption, and analyst distrust. Before any containment action is automated, the detection should be tested, tuned, and measured. If you have not yet defined how you measure detection quality, it is worth aligning the workflow with the same thinking used in measuring detection quality and false positives.
Confidence thresholds are a practical way to structure this. A low-confidence alert may only create a case and enrich context. A medium-confidence alert may notify an analyst and prepare a response, but wait for approval. A high-confidence alert may trigger a limited automated containment action, such as isolating a device or revoking a session token. The threshold should be explicit, documented, and reviewed regularly.
Severity bands should reflect both technical confidence and business impact. A low-severity alert on a non-critical asset may be safe to automate more aggressively than a medium-severity alert on a finance system. Likewise, a high-severity alert involving a privileged account may require a different approval path from a high-severity alert involving a standard user account. This is where security operations and business context need to be linked, not treated separately.
Reducing false positives before automating response is usually the best investment. Improve the detection logic, add suppression for known benign activity, enrich with asset and identity context, and use correlation to distinguish isolated noise from a real incident. If a playbook is built on a weak signal, the automation will amplify the weakness.
Integration patterns for identity, endpoint, email, and network controls
Identity is often the cleanest automation target because it is both central and reversible. Common actions include disabling a user, forcing password reset, revoking sessions, removing group membership, and stepping up authentication requirements. These actions are particularly effective when paired with conditional access, privileged access workflows, and role-based access control. If you are designing that layer, the article on designing Zero Trust architectures with Entra ID is a useful companion because response automation works best when identity policy is already well structured.
Endpoint actions are also common, but they need careful scoping. Isolating a device, collecting triage artefacts, or starting an investigation package are generally suitable automation candidates. More disruptive actions, such as remote wipe or full remediation, should usually require approval unless the use case is tightly controlled. Endpoint automation should also respect device ownership, because the response path for a managed corporate laptop is different from a personal device under a bring-your-own-device policy.
Email security automation can be effective for phishing response. A playbook may search for related messages, quarantine similar emails, remove malicious messages from mailboxes, and block sender domains or URLs. The main risk here is over-blocking legitimate mail, so the workflow should use confidence thresholds and, where possible, a preview or approval step before mass removal.
Network controls can be useful, but they are often the most brittle. Blocking an IP address or domain at the firewall or secure web gateway can help contain active abuse, but the action should be time-bound and reviewed. Network-based automation is best used when the indicator is well understood and the business impact of a false block is acceptable. For many SMEs, it is safer to automate network actions only after the identity and endpoint layers are already working well.
Across all of these integrations, API security matters. Use service accounts with narrowly scoped permissions, store secrets in a vault, authenticate with TLS, and log every action taken by the playbook. If the SOAR platform can make changes in production, it should be treated as a privileged system in its own right.
How to structure approvals, exceptions, and fallback paths
Approval design should be explicit rather than improvised. A common pattern is to define three response classes: fully automated, analyst-approved, and manager-approved. Fully automated actions are low risk and reversible. Analyst-approved actions are operationally significant but time-sensitive. Manager-approved actions are reserved for cases where the response may affect a critical service or a large number of users.
Exceptions should also be documented. For example, a service account used by an application may not be safe to disable automatically even if it matches a compromise pattern. A finance user may have a different approval route during payroll processing. A server in a maintenance window may need a different containment approach from the same server during normal operations. Exceptions should be rare, justified, and reviewed periodically so they do not become hidden policy drift.
Fallback paths are essential when an action fails partially. If a playbook cannot isolate an endpoint because the agent is offline, it should escalate to an analyst and record the failure. If an identity action succeeds but the ticketing integration fails, the case should still retain the response history. If a downstream API is unavailable, the workflow should degrade gracefully rather than stopping silently.
This is one reason to design playbooks as small, composable steps rather than one large monolithic workflow. Smaller steps are easier to test, easier to retry, and easier to observe. They also make it simpler to identify which integration failed and whether the failure is due to permissions, connectivity, rate limits, or an upstream service issue.
Metrics that show whether automation is helping
Automation should be measured against outcomes, not just activity. Mean time to respond, mean time to contain, and analyst effort per incident are all useful metrics. If SOAR reduces the time from alert to containment but increases false positives or creates more manual clean-up, the net value may be lower than it first appears.
Containment time is often the most meaningful measure for response automation. If a playbook can isolate a device or revoke a session in seconds rather than minutes, that is a clear operational gain. Analyst effort is also important, especially for small teams. Measure how many manual clicks, lookups, and handoffs are removed by the workflow.
False positives and missed alerts should be tracked alongside automation success. A playbook that runs frequently but on the wrong events is not a success. Likewise, a playbook that is so conservative that it never triggers is not delivering value. Review the ratio of automated actions to analyst overrides, and look for patterns in the cases that are repeatedly escalated or manually corrected.
Playbook drift is another useful metric. Over time, systems change, integrations break, and business processes evolve. A workflow that worked six months ago may now be incomplete or too aggressive. Periodic testing should confirm that the playbook still behaves as expected, the permissions are still correct, and the response remains appropriate for the current environment.
A practical rollout approach for UK SMEs
The safest way to introduce SOAR is to start with low-risk, repeatable use cases. Good first candidates include alert enrichment, ticket creation, notification routing, and evidence collection. These deliver value quickly and help the team learn how the platform behaves without touching production controls.
The next stage is to automate limited containment for high-confidence events. Examples include revoking a session for a clearly compromised account, isolating a known infected endpoint, or quarantining a malicious email. Each use case should have a written trigger condition, a defined approval path if needed, and a rollback step. It is better to have three well-tested playbooks than twenty loosely defined ones.
Once the team is comfortable, expand into more complex workflows that combine multiple signals. For example, a suspicious login alert might combine identity risk, endpoint posture, and geolocation before deciding whether to step up authentication, disable the account, or simply create a case. This staged approach keeps the automation aligned to operational maturity.
It also helps to align SOAR rollout with broader architecture work. If you are already improving observability, hardening identity, or refining incident response, automation can be introduced as part of that programme rather than as a separate tool project. That keeps the design coherent and reduces the risk of building a workflow that no one can support.
Common pitfalls to avoid in SOAR programmes
The most common mistake is over-automating immature detections. If the alert logic is noisy, the automation will be noisy too. Another common issue is building a workflow that assumes every integration will be available. In reality, APIs fail, credentials expire, and services change. A resilient playbook expects partial failure and handles it cleanly.
Hidden dependencies are another source of trouble. A workflow may depend on a CMDB being accurate, a ticketing system being available, or an identity attribute being populated consistently. If those dependencies are not documented, the playbook can fail in ways that are hard to diagnose. This is why observability matters as much for automation as it does for applications.
Finally, do not let the SOAR platform become a shadow operations layer. Every automated action should be visible, reviewable, and tied to a clear owner. If analysts cannot explain why a playbook acted, or if administrators cannot safely change it, the programme will become difficult to trust. Good automation should reduce uncertainty, not create it.
For organisations that want to strengthen their response architecture without overcomplicating it, the best starting point is usually a small number of high-value playbooks, clear approval rules, and strong identity and endpoint integrations. That gives you a controlled path from alert to action, with enough visibility to keep the system safe and maintainable.
If you are planning where SOAR fits into your wider security architecture, or you want help turning incident response requirements into practical automation patterns, speak to a consultant.
Frequently asked questions
What is SOAR automation?
SOAR automation uses orchestration and scripted workflows to enrich alerts, route cases, and trigger controlled response actions across security tools. It is most useful when the organisation wants repeatable incident handling rather than manual, ad hoc response.
What is SOAR versus EDR?
EDR focuses on detecting and responding on endpoints, while SOAR coordinates actions across multiple tools and teams. In practice, EDR may detect the issue and SOAR may orchestrate the wider response, such as ticketing, identity actions, and notifications.
Does SOAR use AI?
Some SOAR platforms include AI-assisted triage or summarisation, but SOAR itself does not require AI. The core value comes from deterministic workflows, integrations, and approval logic, which are often more reliable than model-driven decisions for response actions.
Is CrowdStrike a SIEM or SOAR?
CrowdStrike is primarily known as an endpoint security and XDR platform rather than a SIEM or a SOAR platform. It can provide detections and response actions that a SIEM or SOAR tool may consume and orchestrate.
Comments are closed